The useful question is not whether AI is fashionable, but whether a defined workflow improves under the organisation’s quality, safety, privacy, cost, and worker-impact constraints.
Tools and models matter, but so do use-case selection, process design, training, governance, worker participation, and measurement. This playbook makes those decisions explicit; it does not promise adoption or productivity gains.
Treat this as a candidate playbook for teams to adapt and evaluate. Organisation size alone does not establish that a rollout pattern will work.
Do not start with licences. Start with a supportable number of bounded workflows, named owners, affected-worker participation, baseline measurements, data rules, and explicit stop conditions.
NIST’s AI Risk Management Framework provides a reference for governing, mapping, measuring and managing AI risk. It does not validate a particular training calendar or adoption target. The worked figures below are invented to show how a rollout decision can change when correction work is counted.
Discover actual practice before designing the rollout
Some staff may already use approved or unapproved AI tools; others may have valid reasons not to. Survey actual use, data handling, accessibility needs, useful practices, failures, and concerns without turning discovery into employee surveillance. Do not infer an adoption gap or competence level from anecdotes.
The playbook matters when the team needs to turn a candidate tool into a documented, governed workflow and determine whether the result is genuinely better.
The first decision: scope
Name the problem: improve output quality, reduce total task effort, create a new capability or reduce a particular cost. Choose one primary outcome and state what must not worsen. A faster draft may fail if correction work moves to another team; higher volume may fail if errors rise.
Be explicit about employment consequences. Do not present a headcount-reduction decision as an open productivity experiment, and do not imply that a pilot promises job security if that has not been decided. Tell affected staff what is fixed, what they can change and who will make the eventual decision.
Picking use cases
Define a workflow, not a department-wide aspiration. This invented candidate illustrates the use-case record:
Task: draft an internal support handoff from authorized ticket fields.
Before: support staff write and check the handoff manually.
Candidate: model drafts; receiving staff verify source facts before use.
Owner: support operations lead.
Primary outcome: lower total effort per accepted handoff.
Must not worsen: missing commitments, privacy exposure, receiving-team load.
Stop: unauthorized data disclosure or an unhandled critical omission.
Decision point: after the planned normal/failure cases and staff feedback
are available, with gaps recorded rather than hidden by a calendar date.
This defines something the team can reject. “Use AI to improve support” does not. Measure the current process before deciding how much improvement would justify the change. Keep draft-generation speed separate from the time required to accept the work.
Picking the right first use cases
Some characteristics of a good first use case:
Concentrated time investment. Pick a task multiple people on the team spend significant time on. For illustration, 30 minutes across 20 people is 10 hours. That arithmetic is not a benefit estimate until review, correction and shifted work are included.
Clear input and output. Tasks with well-defined inputs and outputs are easier to automate than ambiguous ones. “Extract stated decisions, owners and deadlines from an authorized transcript, preserving unknowns” is testable; “summarise this call” still needs a quality contract. “Make our customer experience better” is not.
Low downside risk. Pick tasks where errors are recoverable, not catastrophic. Internal documents over customer-facing emails. Drafts over final outputs. Recommendations over decisions.
Existing measurement. Existing baselines can reduce setup work, but verify that they capture correction effort, quality, worker impact, and shifted work, not only output volume.
Named ownership. Assign someone with time and authority to coordinate the evaluation, collect staff feedback, and stop the workflow when criteria fail. Enthusiasm is useful but does not replace worker participation or accountable ownership.
Don’t pick:
- Use cases where AI is not actually better than current tools.
- Use cases that touch sensitive data without privacy approval in place.
- Use cases with major regulatory implications until you’ve cleared legal.
- “Innovation theatre” use cases nobody actually wants.
Building the workflows
For each use case, the artifact is a workflow: a specific, repeatable process the team uses. Not a vague “use ChatGPT to help.”
A workflow includes:
- The trigger. When does the workflow start?
- The tools. Which AI tool, which model, which integration?
- The prompts. The exact prompts to use. (For consumer tools, the conversation starter. For custom apps, the system prompt.)
- The inputs. What does the human provide?
- The outputs. What does the AI produce?
- The review. Who reviews the AI’s output before it’s used?
- The success metric. How do we know this is working?
Document this in a shared place: wiki, Notion, Confluence. The workflow should be specific enough that a new team member could execute it.
Add one more field: the stop condition. If the output is wrong, if required data is missing, if the task touches sensitive data, or if a required evidence or validation check fails, where does the workflow go? Good workflows define the happy path and the refusal/escalation path.
A candidate pattern is for the owner and a representative, consenting pilot group to build and test the workflow before a wider decision. Choose the group and duration from the affected roles, task frequency, risk, and sample required, not from a universal timetable.
The training problem
Train on the selected workflow and its failure paths. Use invented or explicitly approved cases before private records. A participant should be able to identify an invented commitment, find its source, stop an unsafe handoff and reach the owner without needing to improvise policy.
For the support exercise, supply a ticket with an unspecified deadline and a draft that invents “Friday”. Ask participants to correct it and record why. Then remove a required source field and check whether they use the escalation path rather than filling the gap themselves.
Allow for accessibility needs, language and different job responsibilities. The receiving reviewer needs a different practice task from the person supplying inputs. Set the pilot pace from available review capacity and representative work, not an arbitrary number of weekly prompts.
Policy and guardrails
Before scaling, document the rules, ownership, and escalation path. The policy should address privacy, security, intellectual property, employment impacts, accessibility, output review, and applicable sector rules without framing staff as adversaries.
A baseline policy document includes:
Approved tools. Which AI tools is the team allowed to use for work? (Consumer ChatGPT? Only Teams/Enterprise? Specific apps?)
Approved data types. Define permitted data by system, purpose, role, classification, provider contract, and applicable law. “Public” does not automatically mean unrestricted for collection or reuse; personal or confidential data needs an approved lawful and secure path.
Customer-facing rules. Are AI-generated responses to customers OK? Under what review process? Is disclosure required?
Generated content rules. Can AI-generated content be used for X (marketing, sales, internal)? Is human review required?
Review and accountability. Who reviews AI outputs before they’re used in consequential ways? Who is accountable if something goes wrong?
Logging and audit. What gets logged? Who can access logs? For how long are they kept?
Provider data use. Record whether prompts, outputs, files, feedback, and telemetry may be retained or used to improve models under the exact product, plan, region, and settings. Verify the current contract and controls rather than assuming an enterprise default.
Escalation path. What if someone has a question about whether something is OK?
Policy length follows the risk and organisation. Make the operational rules discoverable, specific, accessible to affected staff, linked to the full governing policies, and owned by someone who can answer questions and update them.
Measuring impact
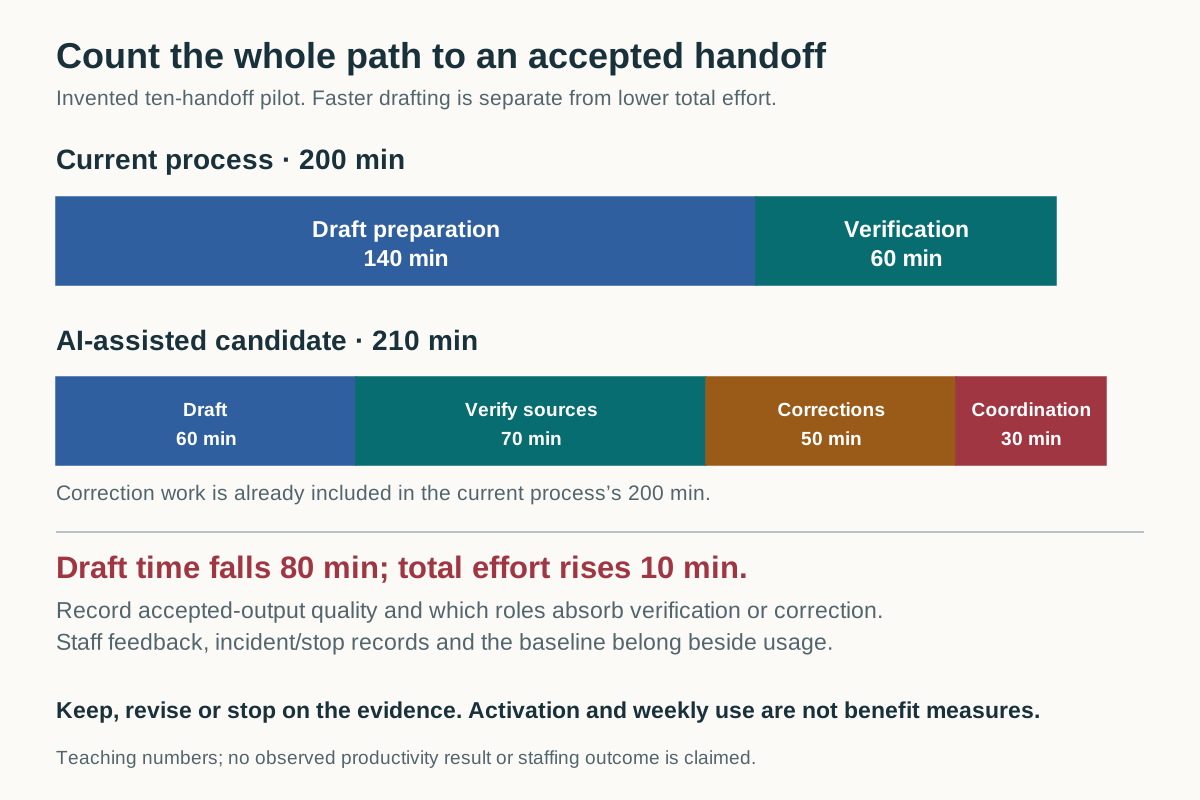
Measure the entire path to an accepted output. This invented ten-handoff batch shows why:
| Effort | Current process | AI-assisted candidate |
|---|---|---|
| Draft preparation | 140min | 60min |
| Source verification | 60min | 70min |
| Corrections | included above | 50min |
| New coordination and failed-run handling | 0min | 30min |
| Total | 200min | 210min |
The candidate drafts faster but uses 10 more minutes overall. These are teaching numbers, not observed results. In a real pilot, use consistent definitions so effort is not counted twice, and record which people absorb the work.
This could still be worth refining if output quality improved and the extra effort is acceptable. It cannot support the claim “we saved 80 minutes” by ignoring the rest of the process. Likewise, license activation and weekly use describe adoption, not benefit.
Record accepted-output quality, correction categories, total effort, affected-worker feedback and incident/stop events beside usage. Compare similar task mixes and explain changes in difficulty or staffing. A before/after difference without those checks is weak evidence of causation.
A staged plan: set dates from evidence
Move through three decisions rather than a fixed rollout calendar:
| Decision | Evidence needed | If it is missing |
|---|---|---|
| Run a bounded pilot | Named owner, permitted inputs/tools, staff participation, baseline and failure tests | Keep the exercise on invented data |
| Keep or revise the workflow | Accepted-output quality, total effort, incident record and feedback from both senders and reviewers | Repair the gap and repeat affected cases |
| Expand the scope | Next role/data/action assessed, support capacity available and rollback tested | Retain the existing boundary |
Choose keep, revise or stop for each use case and record the reason. Expanding to another data class or customer-visible action is a new scope decision, even if the prompt stays unchanged. Later cycles are not automatically faster.
A note on individual vs team adoption
Individual practice may differ from official tooling. Discover it through a voluntary, non-punitive process that distinguishes approved work use from personal experimentation.
Where staff choose to share approved practices, assess them against the same data, quality, security, accessibility, and worker-impact criteria. Credit contributors and do not convert voluntary experimentation into an undisclosed performance expectation.
A top-down rollout can miss useful practice, accessibility needs, and hidden risks. Evaluate existing workflows with their users rather than automatically codifying or suppressing them.
Keep the decision record
Retain the baseline, candidate configuration, measurement definitions, staff feedback, decision and next review trigger. If the workflow is stopped, remove unused access and explain what was learned. A pilot that reveals no net benefit has still answered the question it was designed to test.