Using several AI tools can help when a project has genuinely different stages: finding sources, querying a bounded document set, analysing data, drafting, checking claims, and storing the approved result. It can also create extra failure points. Context gets dropped, model output becomes detached from its sources, and sensitive material is copied into services that were never approved for it.
The useful skill is therefore not loyalty to one vendor or automatic routing to a supposed winner. It is workflow design. Give each stage a measurable purpose, choose an approved tool whose current capabilities fit that purpose, and make every handoff inspectable.
The worked example below follows one dataset through analysis, writing and checking. The other paths show when a handoff needs different evidence. The examples are designs to test, not measured productivity results.
Every additional tool is another data-processing boundary. Before a handoff, confirm that the destination is approved for the data, disclose only what the next step needs, and preserve the source, permission, and review status of the material.
Start with capabilities, not vendor winners
Choose tools by what a stage needs to return. Research needs inspectable sources; document work needs identifiable passages; analysis needs reproducible transformations; drafting needs to preserve checked facts. Storage needs access controls and a version you can recover.
One approved product may cover several stages. A second model is useful only if it adds a demonstrated capability or check. Two models agreeing is not independent confirmation: both may reuse the same source or inherit the same mistaken framing.
OpenAI’s evaluation guidance recommends defining task-specific criteria, choosing representative cases and comparing results. Apply that discipline to the whole handoff, including omissions and review effort, rather than assigning fixed “researcher” and “writer” roles to vendor names.
The shape of a reliable multi-tool workflow
A useful workflow has five properties:
- A stage-level success criterion. Define what the research, analysis, draft, or review step must produce and how you will check it.
- A named source of truth. Identify the authoritative documents and the repository where approved outputs live.
- An explicit data boundary. Record which tools and accounts are approved, which data classes are allowed, and what must be removed or redacted.
- A structured handoff. Pass the objective, selected sources, claims, unresolved questions, constraints, and requested output, not an unexplained block of generated prose.
- A review owner. Name the person who verifies evidence, accepts residual uncertainty, and approves any consequential action.
Two models producing similar text does not create independent confirmation. Their outputs may reflect the same public sources, training patterns, retrieved passages, or framing in your prompt. Treat agreement as a hypothesis worth checking and disagreement as a clue worth investigating. Neither replaces source verification or domain review.
Workflow 1: Research and write with provenance
Use this workflow for an article, memo, brief, or report on a topic that requires fresh evidence.
Step 1: Define the evidence contract. Write the question, audience, date range, jurisdictions, required primary sources, excluded sources, and what uncertainty must remain visible. Decide whether the output is exploratory or ready for publication.
Step 2: Run web research. Use an approved research product and save the report with its source list and retrieval date. Do not hand the whole report downstream yet. Open the sources that support material claims, prefer primary documents, and mark claims as verified, contradicted, unresolved, or background.
Step 3: Build a bounded source pack. Put the reviewed sources, relevant excerpts, and notes into a controlled folder or document-grounded tool. If the tool provides citations, inspect the source for every claim material to the memo and confirm that each cited passage supports the interpretation. A grounded answer can still omit evidence, misread a passage, or overstate an inference.
Step 4: Draft from the reviewed pack. Give the drafting model a handoff such as:
Draft a memo for [audience] from the attached reviewed sources. Preserve the claim labels and source IDs. Do not turn an inference into a fact. If sources conflict or do not answer a material question, retain that uncertainty. Use [structure and voice].
The drafting model can be Claude, ChatGPT, Gemini, or another approved model that performs well on your own examples. The workflow does not depend on a universal writing winner.
Step 5: Challenge the draft. Ask a second pass, in the same or a different model, to map each factual claim to evidence, identify unsupported generalisations, and articulate the strongest credible objection. Then obtain the required editorial review: an authorized reviewer checks the material claims against their sources and decides which changes to accept. Where the owner and publication policy permit expert-AI review, record that review and its evidence; retain any separately required human or specialist gate.
Step 6: Publish the artefact, not just the chat. Store the final version with its source pack, review date, owner, and unresolved limitations. If the evidence changes, you now know what must be rechecked.
The time and quality gain vary with the topic, source quality, tool latency, and amount of human review. Measure them against your previous process rather than promising a fixed turnaround.
When the next tool cannot receive the source
Do not solve a blocked handoff by copying the same data into a different account. A contract-review workflow, for example, may allow a lawyer to use an approved internal system while forbidding transfer to a general chat service. In that situation, keep extraction and review inside the approved boundary. A later drafting stage can receive an authorized issue list only if its wording and destination are also permitted.
If the next stage cannot inspect the necessary evidence, label its work as limited preparation. It cannot provide the missing legal interpretation or factual verification merely because its input came from another model. Escalate the unresolved question to the responsible specialist before a consequential action.
Workflow 2: Data to presentation with reconciliation
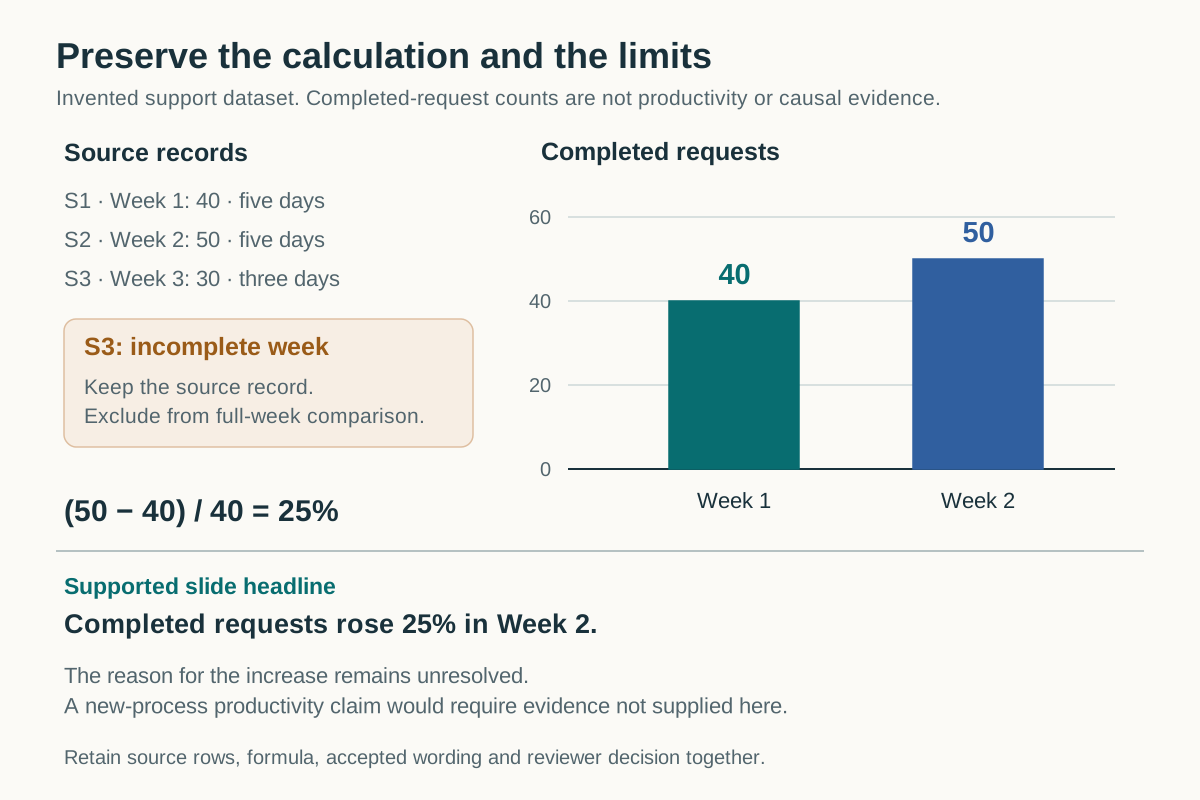
Consider this invented support dataset. The task is to prepare one slide about completed requests, not explain employee performance or infer why volume changed.
| Source row | Week | Completed requests | Measurement note |
|---|---|---|---|
| S1 | Week 1 | 40 | Full five-day period |
| S2 | Week 2 | 50 | Full five-day period |
| S3 | Week 3 | 30 | Three days recorded; week incomplete |
Analysis stage. A spreadsheet or code tool calculates (50 - 40) / 40 = 25% for Week 2 versus Week 1. Week 3 is withheld from a full-week comparison. Keep the source table and formula; do not ask a drafting model to reconstruct them from a chart image.
Handoff to the writer. Send the following packet, with the approved source data or a restricted reference the writer can actually access:
Outcome: one slide for the support planning meeting.
Verified observation C1: Week 2 completed 50 requests versus 40 in Week 1,
a 25% increase. Evidence: S1, S2 and formula (50-40)/40.
Unresolved: reason for the increase; no staffing or complexity data supplied.
Excluded comparison: Week 3 is incomplete (S3).
Instruction: preserve those limits; propose no causal explanation.
Draft check. An author-written acceptable headline is “Completed requests rose 25% in Week 2.” “Our new process improved productivity by 25%” fails: neither the process attribution nor productivity denominator exists in the data. “Volume fell 40% in Week 3” also fails because the periods are not comparable.
Slide check. The chart uses Weeks 1 and 2 with the same unit, a visible axis and a note that these are counts, not a quality or efficiency measure. The source table, calculation, accepted wording and reviewer decision stay together. These checks expose how a numerically correct calculation can become a misleading claim during handoff.
A decision is a different output from a summary
For a vendor choice or product experiment, pass the options, evidence, constraints and unresolved assumptions, not just a previous model’s recommendation. Ask the next pass to identify what evidence would change the choice. The decision owner records the choice and review trigger outside the chat.
If one pass says “launch” and another says “wait”, investigate the assumption causing the disagreement. Model voting does not estimate the probability of business success. A small real-world test may resolve more uncertainty than another critique pass.
Design the handoff packet
A clean handoff is more than copy-paste. Use a small packet with:
- the next step’s objective and acceptance criteria;
- source IDs, links, owners, publication or effective dates, and access classification;
- verified claims, disputed claims, inferences, and unanswered questions;
- the minimum excerpts or data fields needed for the task;
- constraints on use, retention, output, and external actions;
- the requested format and the person who will review it.
Keep the packet and approved output in the project source of truth. Chat history may supply useful context where the product supports it, but its availability, retention, export, and sharing rules differ. Test those properties instead of assuming every conversation is isolated or permanent.
Choose manual or automated transfer deliberately. Manual transfer is not automatically safer, because it can lose provenance or introduce copy errors. Automation is not automatically better, because a connector can expand access or repeat a mistake at scale. Use the option that best enforces the data boundary, schema, logging, error handling, and approval gate for the specific workflow.
Choose tools with evidence
Replace a first-choice cheat sheet with a decision record:
| Criterion | Questions to answer | Evidence or guardrail |
|---|---|---|
| Capability fit | Can it perform this stage with the required file types, tools, language, and output format? | Run representative examples and record failure modes. |
| Data approval | Is this account and feature approved for the data classification and jurisdiction? | Check current contracts, admin controls, retention, training, and sharing terms. |
| Traceability | Can a reviewer recover sources, citations, transformations, model/version, and approvals? | Keep source IDs, logs or exports, and a review record. |
| Evaluation quality | Does it meet the task’s factual, structural, and style criteria? | Use a fixed task set with expected evidence, not model reputation. |
| Latency and cost | Is the end-to-end workflow acceptable at realistic volume? | Measure tool time, human review time, retries, subscriptions, and API usage. |
| Handoff quality | Can the next stage receive the necessary context without excess disclosure? | Test the handoff packet and permission boundary. |
Re-evaluate when a product, model, plan, policy, or data classification changes. Vendor labels age quickly; a documented decision criterion survives them.
When one tool is enough
Multi-tool overhead may outweigh its value when the task has one low-risk stage, one approved tool already meets the acceptance criteria, or the handoff would expose data without adding a measurable check. Continuity can also matter for iterative work, although a structured working document can preserve continuity across tools when a switch is justified.
Start with the smallest workflow that preserves evidence and permissions. Add a second tool only when it contributes a distinct capability or check that you can demonstrate. The goal is not more tabs. It is a better-controlled path from source to reviewed artefact.