Providers expose reasoning in different ways. OpenAI uses reasoning effort and modes on supported models, Anthropic documents adaptive and extended thinking, and Google documents thinking levels or budgets for supported Gemini models. Product labels and parameters change, so choose by current provider documentation and measured task performance rather than a fixed list of model names.
Some reasoning models benefit from a different prompting style from non-reasoning configurations. For OpenAI reasoning models, the current guidance is to start with straightforward prompts and avoid asking for a chain of thought. Treat broader claims about scaffolding, roles, and self-critique as hypotheses to test on your model and workload, not rules that transfer automatically between providers.
The useful question is which failure more reasoning might fix. Missing evidence, a wrong permission boundary and an invalid test cannot be repaired simply by raising effort.
What reasoning controls change
Providers use labels such as reasoning, thinking, effort, and budget for controls that can change token use, latency, and output quality. Depending on the provider and configuration, reasoning content may be hidden, summarised, omitted, or returned in separate blocks. Do not infer a provider’s hidden process from a label or from the style of the final answer.
Reasoning can improve results on some hard, multi-step tasks, but the gain depends on the model, effort setting, prompt, and evaluation. It can also add latency and billed reasoning tokens. The choice between a lower-latency configuration and more reasoning is therefore an architectural decision to benchmark, not a universal upgrade.
The controls are provider- and model-specific. In particular, Anthropic’s current documentation distinguishes manual thinking budgets from adaptive thinking; the same parameter is not accepted by every model. Record the exact supported setting in your comparison, rather than describing both candidates merely as “high reasoning”.
When to test more reasoning
A reasoning model or higher-effort setting can be a relevant comparison. Use these task signals and boundaries when defining the experiment:
- The problem has multiple steps that build on each other. Math, logic, multi-step planning, code that requires tracing state.
- A lower-reasoning configuration keeps failing the same evaluated cases. A reasoning model or higher effort is then a relevant experiment. Compare both configurations on the same cases.
- The task involves careful comparison or trade-off analysis. Multi-criteria decisions, architectural choices, vendor evaluations.
- Your evaluation includes edge cases that lower-reasoning configurations miss. Measure those cases directly rather than inferring reasoning quality from fluent text.
- The task is consequential. Do not select more reasoning merely because the stakes are high. In finance, law, medicine, safety, or production operations, use authoritative sources, qualified review, validated controls, and a documented decision boundary. Then test whether the reasoning configuration improves the cases that matter.
Cases where a lower-reasoning baseline may be competitive:
- Latency-sensitive conversational chat. Use more reasoning only if its measured quality gain justifies the slower interaction.
- Generation and drafting where evaluations show no benefit. A lower-latency configuration may be better for creative iteration; compare output quality rather than assuming that more reasoning helps or hurts.
- Simple retrieval. A grounded lookup or lower-reasoning configuration may meet the quality target with less latency and cost. Verify the source either way.
- Rapid iterative refinement. Lower latency may improve the interaction, but compare final task success rather than counting turns alone.
- Tasks where you need auditable intermediate evidence. Ask for calculations, sources, test results, or other verifiable artefacts. A visible chain-of-thought narrative is not evidence that the conclusion is correct.
A useful decision rule is to increase reasoning only when the expected quality gain is worth the measured latency and cost for that workflow.
Prompt patterns to compare
Use one baseline with the task, relevant context, hard constraints and required evidence. OpenAI’s reasoning guidance recommends direct prompts rather than requesting a chain-of-thought transcript. This is provider guidance, not proof that every structured prompt is inferior.
A procedure belongs in the prompt when it is part of the actual contract: preserve source IDs, apply a specified formula, or return a result in a defined schema. “Think carefully, critique yourself, then think again” does not define an acceptance test. Compare additional scaffolding only when a concrete failure gives you a reason to try it.
Ask for the artifact that allows checking: a calculation, a counterexample, a cited source passage or a runnable test. A plausible explanation of a wrong answer remains a wrong answer.
Worked examples
This invented scheduling problem has an answer you can check without trusting the model:
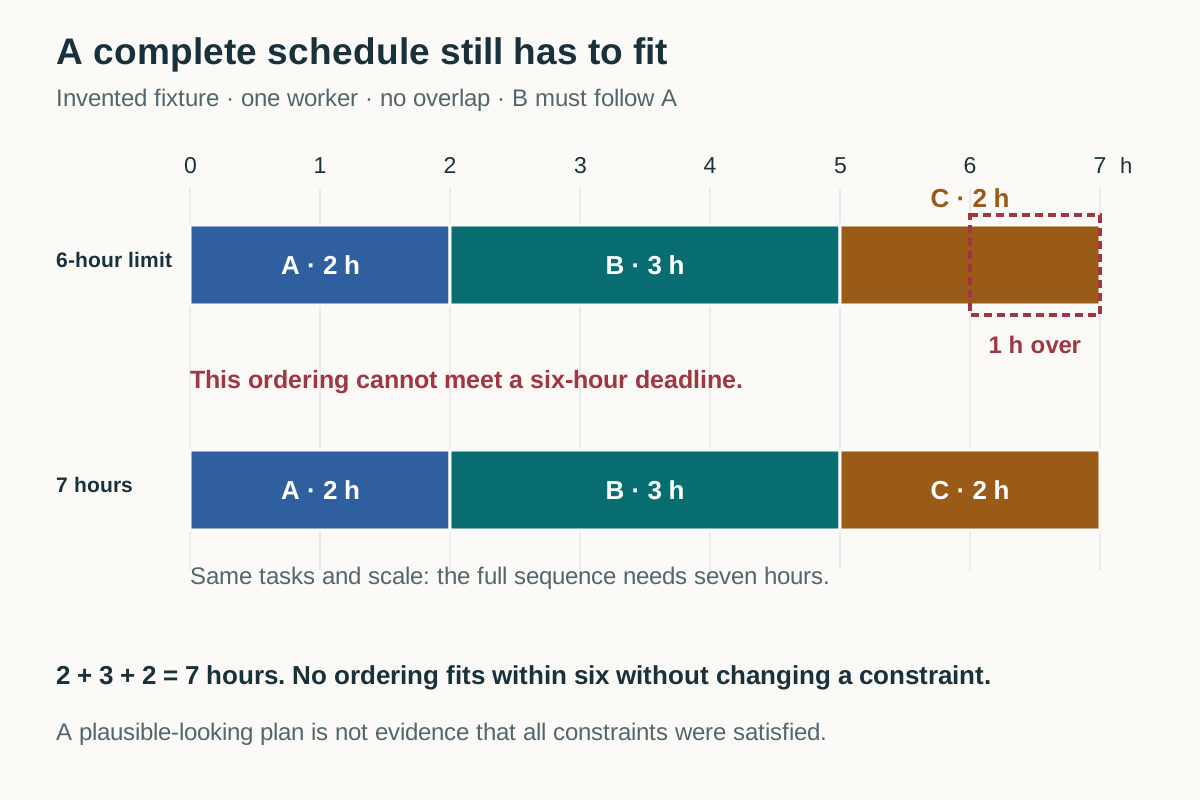
Schedule three indivisible tasks on one worker within a 6-hour window.
A takes 2 hours. B takes 3 hours and starts only after A finishes.
C takes 2 hours and has no dependency. Tasks cannot overlap.
Return a feasible schedule, or show the constraint that makes it impossible.
Do not shorten or split tasks. Give a concise, checkable result.
The total work is 2 + 3 + 2 = 7 hours. With one worker and no overlap, the six-hour window is impossible regardless of ordering. A proposed schedule that places C alongside B fails the explicit constraint. A response saying merely “not enough time” reaches the conclusion but omits the requested evidence.
Make nearby cases before comparing models:
| Change to the invented input | Expected result | What it tests |
|---|---|---|
| Window becomes 7 hours | A 0–2, B 2–5, C 5–7 is feasible | Avoid reflexively repeating “impossible” |
| C becomes 1 hour | A 0–2, B 2–5, C 5–6 is feasible | Use the changed quantity |
| Add a second worker | A 0–2 and B 2–5 on worker 1; C 0–2 on worker 2 | Distinguish dependency from shared capacity |
| B duration is unknown | Ask for the duration or give a conditional bound | Do not invent missing input |
These are author-calculated answers, not observed model scores. They demonstrate how to build discriminating cases. Real scheduling work needs its own constraints and evaluation set.
First compare two supported reasoning settings with this prompt unchanged. Then, if failures justify it, hold the setting constant and add one instruction such as “Check the total single-worker load before proposing a schedule.” Changing both the model and the prompt at once makes the cause of an improvement harder to identify.
Before running, decide what counts as a pass and what latency or cost is acceptable. Record failed and timed-out attempts, not just the answer you chose to keep. For a variable model output, repeated trials help reveal inconsistency; a handful of toy passes does not establish production reliability.
Pitfalls specific to reasoning models
A short list of things that catch even experienced users:
The latency. More reasoning can increase response time, sometimes materially. Measure the actual distribution for your model and workload, including timeouts, rather than planning from a generic estimate.
The cost. Providers account for reasoning differently, and model prices change. Measure billed input, output, and reasoning tokens on representative requests, then compare total task cost rather than assuming a fixed multiplier.
A response hits its generation limits. Reasoning and answer tokens share limits differently across providers. If a response stops early, inspect the provider’s stop reason and token accounting. Then narrow the task or adjust only the supported per-model controls; do not assume that every API accepts a generic thinking budget.
Long, stalled, or unproductive responses. You may observe unusually long latency, timeouts, repetition, or a final answer that misses the task. Record the observable failure and configuration. Then retry within your policy, narrow the task, or compare a different supported setting; do not claim to know the hidden cause from the output alone.
Fluent but unsupported conclusions. More reasoning does not prove correctness. On critical outputs, require sources, calculations, tests, and the assumptions or new evidence that would change the conclusion; self-reported confidence is not a calibrated guarantee.
Variable cost between requests. Reasoning-token use can vary with the task and configuration. Track actual usage rather than assuming each request costs the same or that cost scales predictably with subjective hardness.
A routed workflow to test
Do not route to expensive reasoning because the model says it feels uncertain. Its self-reported confidence is not a calibrated failure detector.
Prefer observable triggers you can evaluate: a required field is missing, a deterministic checker rejects a candidate, the input belongs to a task family with demonstrated baseline failures, or the first attempt reaches its limit. Some of these should trigger a clarification or manual review rather than a second model call.
For the scheduling example, a deterministic capacity check can detect the original impossibility directly. If that check solves the real task, an agent or two-model route adds no value. For more complex constraints, compare a higher-reasoning retry with a single stronger configuration and with a conventional solver. Count the cost and delay of both attempts, including failures.
Use the reasoning comparison record to capture the selected route, evidence and fallback. A higher-stakes task still needs the relevant authoritative sources and accountable review; effort is not a substitute for those controls.
Keep the setting attached to the result
Save the model identifier, supported effort setting, prompt version, tool access, test date and usage data with the comparison. Recheck after a model or prompt change. If the higher setting does not improve the failures that matter within the service target, keep the simpler eligible configuration.