

An AI workflow can appear satisfactory on a few initial examples and later fail on different inputs or after a model, prompt, retrieval, tool, or policy change. Without retained inputs, outputs, versions, and acceptance criteria, the team cannot establish what changed or whether the candidate regressed.
One common cause is missing measurement. The underlying model, prompts, retrieval corpus, tools, or input distribution may have changed. Without a retained baseline and release checks, the team may not detect the change until users complain.
The discipline is evaluation: systematic measurement of an AI workflow against explicit requirements. A small team can begin with a spreadsheet when manual execution is reproducible, while consequential or high-volume systems may require automated evaluation, statistical design, and qualified domain reviewers.
This article covers what evals are, why they matter, and how to set them up for any AI workflow without being an engineer.
Evals are not reporting theatre. A useful eval creates a decision: ship, hold, roll back, or investigate. If a score cannot change what the team does, simplify the eval until it can.
What evals are (and aren’t)
An eval is a way to measure how good your AI’s output is, systematically, against examples you control.
The components:
- A dataset. A set of inputs (the things your AI processes).
- Expected behavior. What you want the AI to do with those inputs.
- A scoring method. How you measure if the AI did it right.
- A run/report. Process the dataset, score each output, summarize the result.
The point is to have a repeatable way to ask: “is the AI doing what I want, at the quality I expect?” and to spot when the answer changes.
Evals are not:
- One-off testing during initial build.
- Spot-checking when something seems off.
- User feedback alone, although approved feedback can supply cases and outcome measures.
- Vibes (“the output feels right”).
Repeatable evals use defined inputs, configuration and scoring. Run them before material changes and on a monitoring cadence suited to the workflow; a schedule alone does not make a test useful.
Start with the simplest method that preserves evidence
A controlled spreadsheet can hold case IDs, permitted inputs, expected behavior, outputs, configuration versions and reviewer decisions. Use protected references when the underlying cases contain private data. Permission to operate a workflow does not automatically permit copying its records into a new evaluation service.
Start there if manual execution is reproducible. Move to automation when volume, trace capture or release integration requires it. The tool does not determine whether your sample covers the failures that matter.
The four eval patterns
There are four common eval patterns. Each fits a different type of workflow.
Pattern 1: Exact match
Use when there’s a single correct answer.
Example workflow: classifying customer support tickets into 8 categories.
Dataset: labeled tickets covering the intended categories and boundary cases. Scoring: AI’s answer either matches the correct category (1 point) or doesn’t (0 points). Output: % correct.
Exact match is appropriate only when one canonical representation is required. Normalise permitted formatting differences and do not use it as a proxy for semantic or domain correctness.
Pattern 2: Reference comparison
Use when there’s a known good answer to compare against.
Example workflow: drafting product descriptions.
Dataset: products with reviewed reference descriptions and source facts. Scoring: how close is the AI’s description to the reference, on dimensions like accuracy, tone, completeness?
You can score this manually (a human reads both and scores 1-5) or with an LLM judge (next pattern). A reference is useful only when it is correct, current, representative, and not treated as the sole valid wording.
Pattern 3: LLM-as-judge
Use when the output has many valid forms but quality is judgeable.
Example workflow: generating personalized sales emails.
Dataset: invented or authorized profiles with checked facts. Scoring: an LLM acts as a judge; given the input and the output, score on dimensions like specificity, professionalism, length, voice match.
LLM-as-judge is powerful but requires careful prompt design. A common pattern:
You are evaluating a sales email for quality. Score it on these dimensions:

1. Specificity (1-5): Does it use relevant facts supported by the supplied profile? Reject invented personalization regardless of style.
2. Professionalism (1-5): Does it sound like a peer rather than spam?
3. Length appropriateness (1-5): Is it concise (40-80 words)?
4. Voice match (1-5): Does it match our voice (direct, no buzzwords)?

For each dimension, give the score and a one-sentence reason.

Output JSON: {"specificity": {"score": N, "reason": "..."}, ...}

Prospect profile: [input]
Email to evaluate: [output]
An LLM judge applies one model and rubric repeatedly, but can be biased, position-sensitive, inconsistent across runs, or wrong in correlated ways. A judge you have not checked is a second opinion of unknown quality. Calibrate it against qualified human labels and keep monitoring it, following the same general discipline described in OpenAI’s evaluation guidance and Anthropic’s evaluation guidance:
- Create a representative human-labeled set. Reuse real cases from the review queue, cover important classes and edge cases, separate calibration from final evaluation, and document who was qualified to label each dimension.
- Run the judge on the same set and inspect every disagreement. Report a confusion matrix or per-score agreement, not only one average. Disagreement may come from the rubric, the human label, or the judge; investigate rather than assuming which one failed.
- Weight the direction and consequence of errors. A judge that passes harmful output may be unacceptable even when aggregate agreement looks high. Set release criteria from the cost of false accepts and false rejects.
- Recalibrate after any relevant change to judge model/version, prompt, rubric, language, input distribution, or policy. Determine sample size from class prevalence and the confidence you need; a fixed example count is not universal.
Do not let an LLM judge be the sole release gate for medical, legal, regulated financial, child-safety, construction, or other high-consequence outputs. Those dimensions require qualified domain reviewers and risk-appropriate validation; editorial and engineering review alone are insufficient.
Pattern 4: Property check
Use when you can express what “good” means as specific testable properties.
Example workflow: generating product titles for an e-commerce store.
Dataset: representative products with known attributes. Properties to check on each output:
- Length is 30-70 characters.
- Includes the brand name.
- Includes at least one of the product’s key attributes.
- Doesn’t use forbidden marketing words (“amazing”, “best”, “revolutionary”).
Each property is a yes/no test. Score = % of properties passing across all outputs.
Property checks are useful for explicitly encoded constraints. Passing them says nothing about unencoded requirements, so combine them with the other checks the risk analysis requires.
How to set up your first eval
A practical, non-engineer-friendly setup:
Step 1: Pick the workflow
Choose one workflow. Don’t try to eval everything at once. Pick the one you most worry about quality on, or the one that’s most consequential.
Example: “the AI that classifies inbound customer support tickets by topic.”
Step 2: Build the dataset
Select enough examples to exercise the decisions you need to make, and document uncovered classes. A small starter set discovers mistakes; it does not establish a precise reliability rate. Include:
- Easy cases (clearly category A).
- Hard cases (could be A or B).
- Edge cases (don’t fit any category cleanly).
- Common variations (different phrasing of the same intent).
Capture them in a spreadsheet or Google Sheet:
| ID | Input | Expected Output |
|---|---|---|
| 1 | ”My password isn’t working" | "account-access” |
| 2 | ”I want to cancel my subscription" | "billing” |
| 3 | ”Your latest update broke my workflow" | "bug” |
| … | … | … |
Version this set so baseline and candidate comparisons use the same cases. Add emerging cases deliberately and distinguish tuning cases from held-out evaluation; repeated tuning against the final set weakens the comparison.
Step 3: Define scoring
For each example, what counts as a correct answer? Be precise.
For classification: exact match on category. For content: a 1-5 score on each of 2-4 named dimensions. For extraction: each field correct/incorrect.
Write down the scoring rubric. Stick to it.
Step 4: Run the workflow on the dataset
Run your AI workflow on each example in the dataset. Capture the output in a new column.
For classification, run the approved workflow on authorized test inputs and copy the result into the controlled scorecard. Do not add a spreadsheet AI extension without checking its separate data path.
For more complex workflows, automate the same versioned execution and evidence collection in an approved environment. Keep raw case access restricted.
| ID | Input | Expected | Actual |
|---|---|---|---|
| 1 | … | “account-access" | "account-access” |
| 2 | … | “billing" | "billing” |
| 3 | … | “bug" | "feature-request” |
| … | … | … | … |
Step 5: Score
For exact match: add a column “match” with 1 if Expected = Actual, 0 otherwise. The sum is the number of matches. Divide by the number of evaluated cases to get accuracy; multiply by 100 for a percentage. Report that denominator and separate excluded or failed cases rather than silently dropping them.
For LLM-as-judge: run a judge prompt for each output. Capture scores.
For property check: run each property as a separate test. Aggregate.
Example scorecard and decision
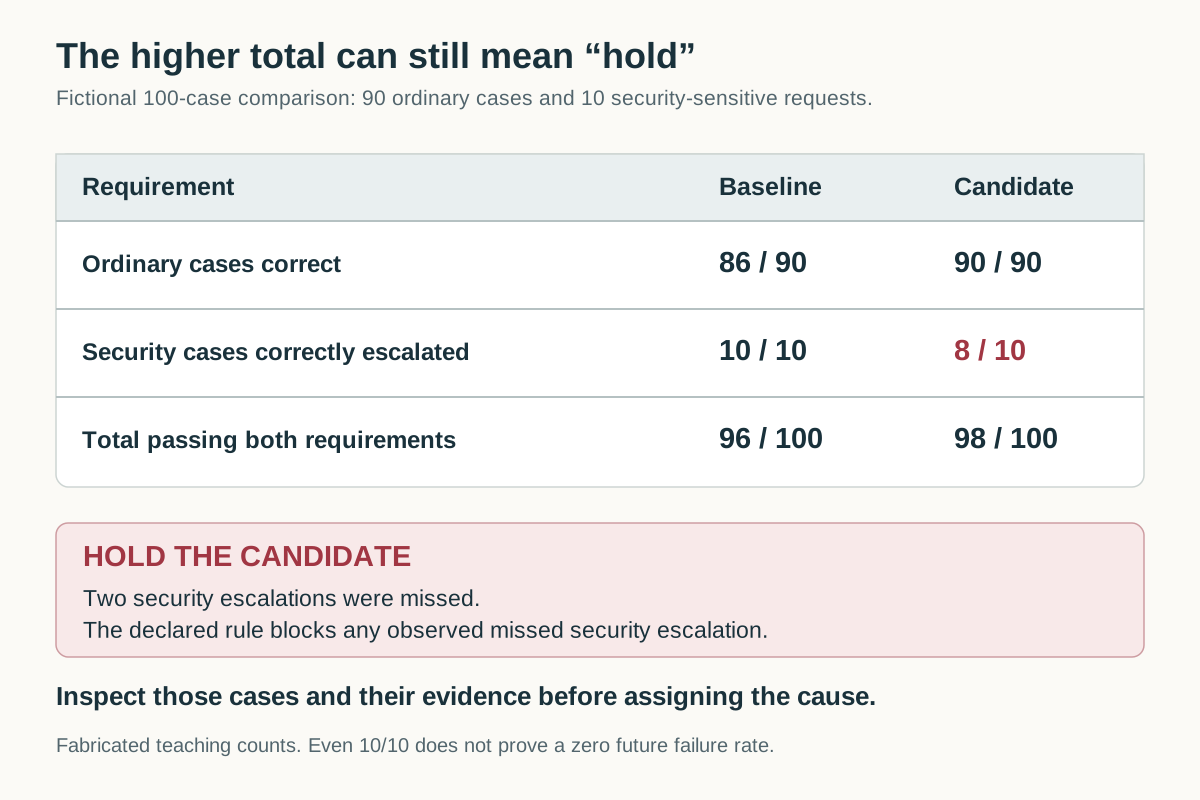
This invented classification comparison has 100 cases: 90 ordinary questions and 10 security-sensitive requests. The required behavior is a correct category plus specialist escalation for the security cases.
| Result | Baseline | Candidate |
|---|---|---|
| Ordinary cases correct | 86/90 | 90/90 |
| Security cases correctly escalated | 10/10 | 8/10 |
| Total cases passing both requirements | 96/100 | 98/100 |
The candidate’s higher total hides two missed security escalations. If the predeclared rule blocks any observed missed security escalation, hold the candidate. Inspect those two cases before deciding whether the model, prompt, policy gate or reference labels caused the failure.
These are fabricated teaching counts, not model measurements. Even 10/10 does not prove a zero future failure rate. The sample’s coverage and size limit what you may infer.
Your scorecard should therefore name blocking failures separately from average quality. Define acceptable performance from the consequence and the decision the evaluation supports, rather than copying 90%, 95% or 4/5 thresholds from an example.
Step 6: Schedule
Run the evaluation on a cadence tied to task volume, model and prompt changes, incidents, and input-distribution drift. Run the relevant release suite before deploying any change.
Assign an owner and enough review time to inspect failures rather than merely recording an aggregate score.
The companion scorecard records the dataset, blocking failures and release decision without preset thresholds.
Add a release gate
Evals matter most when they sit in front of change. For any AI workflow that touches customers, operational records, or team decisions, use a small release gate:
- Baseline. Current production workflow has a recorded score.
- Candidate. New prompt, model, tool, or workflow step is run against the same eval set.
- Comparison. The candidate must preserve safety and regression scores, and must not reduce the primary quality score beyond the agreed tolerance.
- Decision. Ship, hold, revise, or roll back. Record the reason.
- Post-release check. Re-run on a small sample of real cases after launch.
This does not need to be automated on day one. A spreadsheet with a named approver is enough if it consistently prevents unmeasured changes from going live.
What to do when scores drop
The point of evals is to catch quality decay. When it happens, you investigate.
A simple investigation:
Step 1: Identify the failing cases. What specifically went wrong?
Step 2: Look for patterns. Are the failures clustered (similar inputs)? Or scattered (different types of inputs)?
Step 3: Inspect the evidence. Compare source coverage, labels, versions, tool results and execution errors. Clustered and scattered failures are clues, not diagnoses; either can have several causes.
Step 4: Hypothesize the cause.
- Did the underlying model change recently? Check the provider’s changelog.
- Did the prompt change recently? Revert and test.
- Did the input distribution change? Look at recent real data.
- Did the dataset go stale? Refresh examples.
Step 5: Test the fix. Make one change. Re-run the eval. Did it recover?
This systematic approach beats panic and guesswork.
Building the dataset over time
Your initial dataset is a starting point. Improve it over time by:
Adding real failure cases. When a real customer/user case produces a bad output, add it to the eval set. Now it’s a regression test; you’ll catch this specific failure if it happens again.
Pruning stale cases. As your workflow evolves, some test cases become irrelevant. Remove them.
Expanding coverage. A set with 20 account-access tickets and 1 billing ticket may reflect real traffic, but gives little evidence about billing behavior. Keep a production-representative set or documented traffic weights for aggregate reporting. Add an intentionally enriched billing and other critical-case set for diagnosis and release gates; report those slice counts and outcomes separately. Do not treat the enriched mix as a production accuracy estimate.
Adding edge cases as you find them. New customer complaint patterns, new product features, new categories.
A good eval dataset is alive; it reflects current reality, not historical reality.
Common mistakes
A few patterns that cause eval programs to fail:
Mistake 1: Delaying all evaluation while seeking a perfect suite. Start with the smallest set that exercises material normal and failure paths, document what it does not cover, and expand it based on risk and observed failures.
Mistake 2: Only evaluating happy paths. All-easy examples don’t catch real failures. Include hard cases, edge cases, and known previously-failing cases.
Mistake 3: Unversioned eval-set drift. Keep a stable comparison set when useful, but add emerging inputs and known failures deliberately. Version every dataset and report results by version so coverage can evolve without pretending scores are directly comparable.
Mistake 4: Trusting the LLM judge blindly. LLM judges have biases. They overweight surface features (length, format). Calibrate the judge against human judgment regularly. Investigate disagreements: the judge, rubric or reference label may be wrong. Do not automatically change the judge to match an unexamined opinion.
Mistake 5: Scoring without action. Running evals weekly but never acting on the data is theater. The point is to catch and fix issues. If a drop doesn’t trigger investigation, you’re wasting your time.
Mistake 6: Evaluating just one dimension. “My eval shows 95% accuracy!”; but maybe response quality has gotten worse, or response time slower, or hallucination rate higher. Track multiple dimensions where they matter.
Tools that help (but aren’t required)
Choose evaluation software by approved data location, access control, model support, reproducible execution, reviewer workflow, exports and integration with release checks. Try importing your own small case set and reproducing one baseline/candidate comparison before migrating the entire program.
Preserve access to results outside a vendor dashboard. A changed subscription or integration should not erase the evidence behind a release decision.
Start bounded, then earn broader coverage
Evaluations provide evidence about defined cases at a point in time. They reduce blind spots but do not by themselves make a workflow trustworthy or detect every form of drift.
You can begin a low-risk manual pilot without specialised infrastructure. Statistical claims, automated release systems, and high-consequence domains require the corresponding engineering, measurement, and domain expertise.
Pick one bounded workflow. Define the decision the evaluation must support, assemble representative examples, run it reproducibly, inspect individual failures, and record the limits of the evidence.
Improvement is not guaranteed. A versioned evaluation makes it possible to show whether a candidate changed measured quality, safety, cost, or latency, and to hold or roll it back when the evidence is insufficient.





