Inference cost is a workload property: model and region, uncached and cached input, generated and reasoning tokens, tools, retries, concurrency, storage, and human review all matter. Start from billed usage and traces rather than an industry savings claim.
Current prices and cache rules change frequently. Re-check the official OpenAI pricing, Anthropic pricing, and Gemini pricing pages before using any cost model.
Start with one workflow and one billing period. Routing is only one possible intervention; multi-model orchestration covers its separate evaluation and data-boundary requirements.
The cost stack
LLM costs come from:
- Input tokens. What you send to the model. Includes system prompt, context, user query.
- Output tokens. What the model returns. The input/output price ratio varies by provider, model, batch mode, and cache state.
- Reasoning or hidden-compute charges. Provider reporting and billing treatment varies; use the billed usage fields and current price sheet rather than assuming parity with visible output.
- Tool definitions and tool use. Schemas may add input tokens, while hosted tools or external services may have separate charges.
- Retries and failed work. Some failed or abandoned calls incur usage; classify failure points from provider billing and traces.
Optimization works at each layer.
Prompt caching
Caching can be a major lever when requests share an eligible prefix and the workload produces a high hit rate.
Read each provider’s current cache documentation for minimum prefix size, write/read charges, expiry, routing constraints, and observability.
At a high level, an eligible repeated prefix may be reused within a provider-defined window. The exact semantics are not portable across providers.
Practical implementation:
Structure your prompts so static content comes first, dynamic content last:
[CACHED: 10K tokens]
- System prompt
- Tool descriptions
- Minimum authorised context eligible for reuse
- Versioned source material whose access and freshness remain valid

[NOT CACHED: 1K tokens]
- Conversation history (changes each turn)
- Current user query
Whether this prefix is eligible and how it is billed depends on the selected model and provider.
Savings equation:
For a period, sum mutually exclusive billed categories: uncached input, cache creation, cache reads and billable output, each multiplied by its applicable unit rate. Add separately metered tools and storage. If a provider reports total input plus cached input as a subset, subtract that subset before pricing uncached input. Do not add reasoning tokens again if they are already included in billed output.
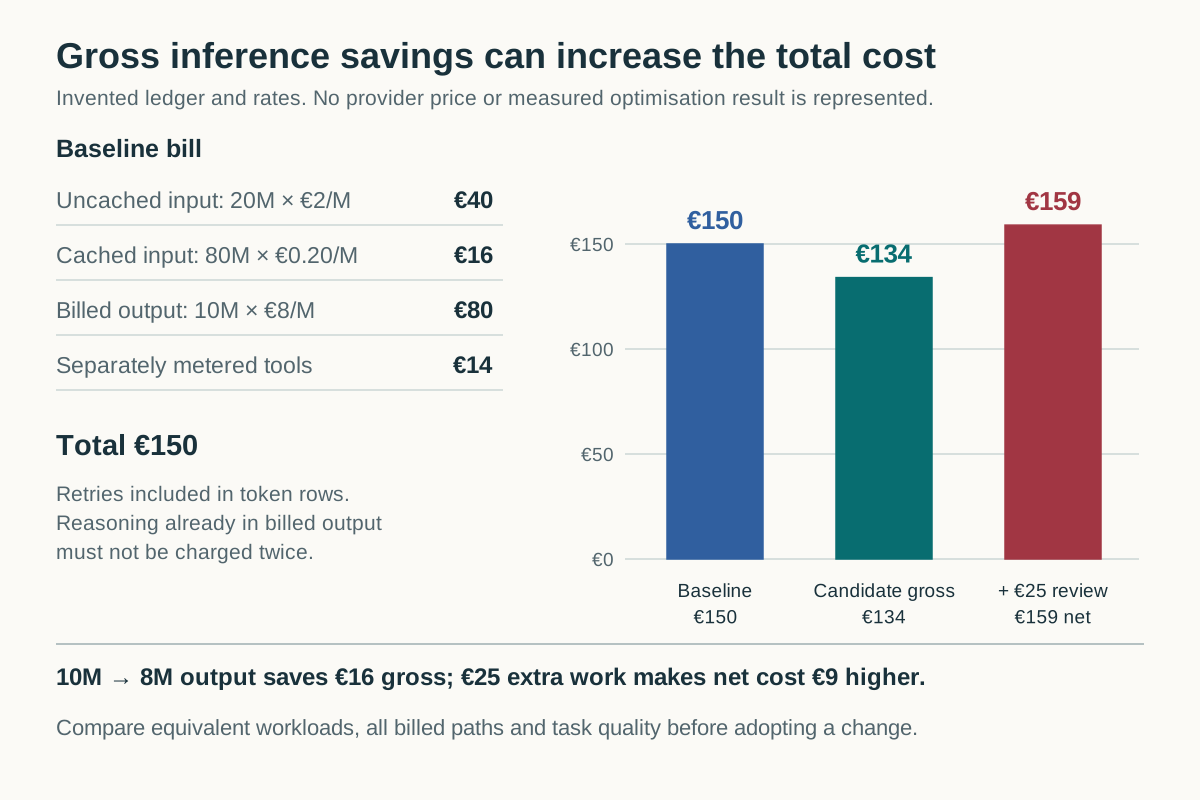
This invented ledger uses rates solely to show the arithmetic, not any provider’s prices:
| Category | Period usage | Illustrative rate | Cost |
|---|---|---|---|
| Uncached input | 20 million tokens | €2/million | €40 |
| Cached input | 80 million tokens | €0.20/million | €16 |
| Billed output, including any billed reasoning | 10 million tokens | €8/million | €80 |
| Separately metered tools | Period total | €14 | €14 |
| Total | Includes retries in the token rows | €150 |
Output is the largest token line here. If a controlled candidate reduces it to 8 million while everything else stays equal, gross cost becomes €134, a €16 reduction. If additional review/operating work costs €25, net cost becomes €159: the supposed saving is a €9 increase. These figures are illustrative and assume the quality bar is met; they are not an observed optimisation result.
Populate it with billed token counts and the current price sheet. Compare equivalent time windows and include cache misses.
Implementation discipline:
- Identify static vs dynamic parts of prompts.
- Place static parts first.
- Use cache markers where the provider supports them (Anthropic) for explicit control.
- Measure cache hits and misses. Low reuse can reflect expiry, minimum size, routing, traffic pattern or configuration as well as prefix changes. Diagnose the billed fields before changing the prompt.
Prioritize caching only after the trace shows repeated eligible input is a leading cost line.
Output length control
Output tokens may be a leading cost line. Confirm that in usage data before optimizing response length.
Strategies:
Explicit length instructions.
Respond in at most 100 words.
Models may still violate a prose length instruction. Enforce and evaluate the limit, and report the measured token and quality change rather than promising significant savings.
Structured output.
When the required response is short structured data, a strict schema can reduce irrelevant prose. It does not eliminate invalid output, oversized field values, retries, or truncation risk; validate every result.
Provider output-token cap.
Set the current API’s output cap from measured task needs and leave headroom for valid completion. Parameter names and semantics differ by API and model; an overly small cap can truncate structured output and cause more calls.
Format constraints.
A format instruction can change length, but a bullet list can be longer than a concise paragraph. Compare tokens and task coverage rather than assuming a saving.
Bullet over prose.
Bullets may reduce connective prose for some responses. Measure token counts; a verbose bullet list can be longer than a concise paragraph.
No preamble.
“Skip introductory phrases. Get straight to the answer.” Models often start with “Great question…” or “Let me explain…”, wasted tokens.
Measurement example:
For a summarization workflow, compare default and constrained outputs on the same documents. Report billed output tokens, factual coverage, readability, user follow-up rate, and any truncation. A lower token count is not a saving if users need another call.
Batching
When you’re processing many items, batch them.
Async batching at the API level.
Some providers support asynchronous or batch products, sometimes with different prices, completion windows, limits, and data-handling terms.
- OpenAI and Anthropic both document asynchronous batch products. Verify the current discount, completion window, limits, and data-handling terms on their official pricing and batch pages.
If backlog work does not need an interactive response, compare current batch pricing and completion behavior with the synchronous path.
In-prompt batching.
Process multiple items in one LLM call when possible.
Instead of:
[10 separate calls, each classifying one ticket]
Do:
[1 call, classifying 10 tickets in one prompt]
The single call has more item input but may reuse one set of fixed prompt overhead. It can reduce total tokens in some workloads; separators, longer outputs, retries, and batch-level failure can erase that saving.
Caveat: batching can change quality, ordering, truncation, and failure isolation. Sweep batch sizes on representative inputs instead of adopting a universal range.
Caching beyond prompt caching
Beyond the model provider’s prompt caching, application-level caching:
Response caching. For an approved scope and complete set of response-affecting inputs, reuse a prior response when its freshness and semantics remain valid. Non-determinism means this is a product decision, not an identity law.
import hashlib
import json

def stable_sha256(value):
    payload = json.dumps(value, sort_keys=True, separators=(",", ":"))
    return "llm:" + hashlib.sha256(payload.encode("utf-8")).hexdigest()

def cached_call(scope, authorization_epoch, source_revision,
                prompt_version, prompt, model, params, ttl=3600):
    # Canonicalize all response-affecting inputs and include tenant/user scope
    # where a shared answer is not explicitly safe. Use a stable cryptographic
    # digest rather than the process-randomized built-in hash().
    # Conceptual sketch: authenticate/authorise before entering this function.
    # Derive scope and current revocation epoch in trusted host code.
    cache_key = stable_sha256({
        "scope": scope,
        "authorization_epoch": authorization_epoch,
        "source_revision": source_revision,
        "prompt_version": prompt_version,
        "prompt": prompt,
        "model": model,
        "params": params,
    })
    cached = redis.get(cache_key)
    if cached:
        return json.loads(cached.decode("utf-8"))
    response = call_llm(prompt, model, params)
    redis.set(cache_key, json.dumps(response), ex=ttl)
    return response
This is conceptual Python: redis and call_llm are application dependencies, not a complete runnable service. The host must check current access before every cache hit; a TTL alone does not handle revoked permission. For eligible queries, a populated valid hit can avoid a repeat call. Define freshness and invalidation, isolate scopes, prevent cache stampedes, and do not cache sensitive or personalized output without approval.
Embedding caching. Computed embeddings cached.
Retrieval result caching. Search results for a query cached for short periods.
Tool result caching. Tool call results cached if the underlying data doesn’t change often.
Cache layers can reduce calls when hits are valid, but storage, invalidation and stale-result failures can outweigh that benefit.
Budget guards
Beyond optimization, enforce hard budgets to prevent runaway costs.
Per-request budget. Maximum tokens per request. Stop if exceeded.
Per-user budget. Daily or monthly cost cap per user. Throttle when approaching.
Per-feature budget. Each feature has an owned budget and a tested response when a workload-specific threshold is exceeded.
Global budget. Total daily/monthly limit. Pause non-essential work near limits.
These controls do not prove savings. They bound or redirect spend and can also reduce availability, so test alerting, throttling, downgrade, queueing, and circuit-break behavior for essential and non-essential workloads.
A cost-reduction experiment template
Use the inference cost experiment ledger. Freeze the workload, accepted-result definition and current price sheet before changing one leading cost line. Include failures, retries, fallbacks and additional user calls in both runs.
| Trace finding | Candidate experiment | Regression to inspect |
|---|---|---|
| Repeated eligible input dominates | Provider prompt caching | Expiry/misses, data boundary, total billed categories |
| Output dominates | Shorter output contract and evaluated cap | Missing conditions, truncation, extra calls |
| Narrow task uses an expensive route | Smaller model or deterministic extractor | Rare-class errors, fallback cost, forbidden data route |
| Repeated answer with stable authorised sources | Scoped response cache | Revocation, source updates, tenant isolation |
| Backlog tolerates delayed completion | Async batch | Completion window, failure isolation, storage and eligibility |
Do not add speculative calls or stream unvalidated intermediate content merely to make a cost chart look better. Speculation can improve latency while increasing spend. Streaming changes delivery timing; it does not itself reduce billed tokens.
Choose a sample and uncertainty treatment capable of detecting a meaningful quality regression. Report gross inference change, net operating change and remaining uncertainty separately. If no candidate clears the quality and economic bar, keep the baseline or reconsider the feature.
Pricing and capability drift
A note on the broader trend.
Provider prices, model capabilities, batch products, cache rules, and hosted-tool charges change on vendor schedules. This article does not establish a universal historical trend or forecast.
Re-run the cost and quality model after material price, model, contract, or workload changes. Do not assume a currently unprofitable workflow will become profitable, or that future list-price reductions will rescue an inefficient design.