The pitch is compelling: rent or own accelerators, serve an open-weight model, and replace a variable API bill. But models are not automatically equivalent, GPUs do not stay fully utilized, and the serving stack becomes your security and reliability responsibility.
This is a cost-modeling guide, not a benchmark. Review the current vLLM documentation, vLLM security guidance, SGLang documentation, and Hugging Face TGI documentation before selecting a server. Benchmark supported versions on the target hardware.
The calculation below uses invented inputs to show where costs cross and why capacity can invalidate that crossing. Replace every input with dated quotes, measured workload evidence and your own operating costs.
When self-hosting makes sense
Investigate self-hosting when a supported model meets the task bar and there is a concrete reason to own the serving boundary: a required model variant, an approved data-locality requirement, or a plausible economic advantage at measured utilisation. Those reasons are hypotheses to test, not a checklist count.
Managed inference remains a candidate when it satisfies the data contract and quality bar with less operational ownership. Spiky traffic, scarce operations capacity and required provider-only capabilities can favour it. A sensitive workload does not automatically require self-hosting, and owning hardware does not automatically make the data flow compliant.
The cost math (carefully)
Build three current, quality-equivalent scenarios: closed-model API, managed open-weight serving, and self-hosting. Do not compare models until they pass the same task evaluation.
For each scenario, calculate:
monthly total = metered inference or dedicated capacity + storage + network + observability + support + security/compliance + engineering + expected incident loss
For metered APIs, inference comes from billed uncached input, cache writes/reads, output/reasoning tokens, tools, batches, and retries. For self-hosted or managed dedicated capacity, the accelerator cost pool must include utilized, idle, headroom, rollout, and failure/fallback capacity; do not add a second “inference” charge unless the contract has a separate mutually exclusive meter. Use benchmarked requests per accelerator-hour at the required latency and availability to allocate that capacity cost to workload units, not the vendor’s peak throughput.
Run sensitivity analysis on volume, peak-to-average ratio, model quality, accelerator price, utilization, staff time, and migration cost. The break-even point is where the quality-equivalent net costs cross under a plausible range of assumptions.
A filled break-even example
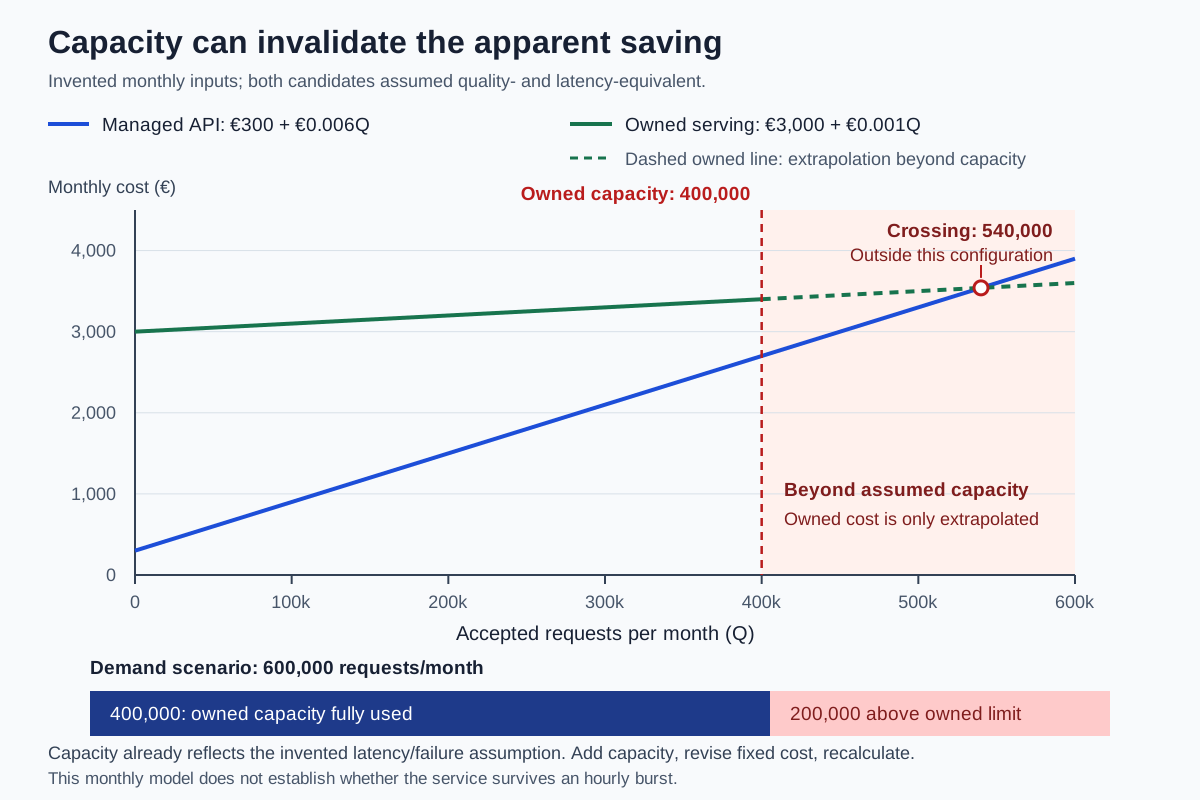
These are invented monthly inputs in euros, not prices or benchmark results. Assume both candidates already meet the same quality and latency bar for an identical request mix. Let Q be accepted requests, with retries and failed attempts included in each cost estimate.
| Cost component | Managed API | Owned serving |
|---|---|---|
| Fixed operations and observability | €300 | €3,000, including capacity, spare/headroom and staff |
| Variable cost per accepted request | €0.006 | €0.001 |
| Monthly cost | 300 + 0.006Q | 3,000 + 0.001Q |
The lines cross at Q=(3,000−300)/(0.006−0.001)=540,000 accepted requests/month. At 100,000 requests, managed costs €900 and owned serving €3,100. At 600,000, they cost €3,900 and €3,600 respectively, a €300 advantage for owned serving under these assumptions.
Now suppose the tested capacity under the required tail-latency and failure conditions is only 400,000 requests/month. The apparent 540,000 crossing lies outside that configuration’s capacity. Adding capacity changes the fixed cost and requires a new calculation. A monthly total also cannot establish whether the service survives an hourly burst.
Migration cost matters too. An invented €12,000 transition cost would take 40 months to recover at €300/month if demand and all other costs stayed fixed. That payback is conditional, not a forecast. Record both the steady-state crossing and the transition horizon in the hosting comparison worksheet.
The operational cost
Beyond raw inference cost, the operational cost of self-hosting.
Initial setup:
- Picking the right inference server (vLLM, TGI, SGLang).
- Configuring for your model and hardware.
- Setting up GPU infrastructure (cloud or owned).
- Networking, security, observability.
- Quantization and optimization.
Estimate initial delivery from a scoped work breakdown, hardware/provider lead time, security review, benchmark matrix, availability design, and the team’s observed throughput. This article does not assert a transferable engineer-week range.
Ongoing operations:
- Monitoring (latency, throughput, errors, GPU utilization).
- Capacity planning.
- Upgrades (new model versions, inference server updates, security patches).
- Incident response (GPU failures, OOM crashes, software bugs).
- Scaling (more GPUs as load grows).
Record actual ownership across platform, ML, security, and on-call work. A fractional-FTE assumption is not portable across organizations.
Hidden costs:
- GPU price volatility.
- Cloud egress costs if hybrid.
- Specialty expertise (CUDA, quantization, optimization).
- Replacement / failure costs for owned hardware.
Use the organization’s fully loaded labor rates and opportunity cost. Token-price savings are not net savings until operational ownership is included.
The inference servers
Shortlist engines that support the exact model, hardware, quantisation and API contract. vLLM and SGLang are candidates, not automatic production defaults. Include security, upgrade, export, admission-control and recovery tests alongside throughput. For example, vLLM’s security guidance distinguishes API-key-protected inference routes from other exposed endpoints; an API key alone is not a complete network boundary.
Hardware choices
The GPU question:
Accelerator generations, memory capacities, and rental prices change quickly. Obtain current quotes for the required region and commitment term.
Compare memory capacity and bandwidth, supported numeric formats, interconnect, software compatibility, quota, regional availability, failure behavior, and price. Spot or preemptible capacity belongs in the model only with interruption handling and a measured recovery path.
Quantization
Quantization is one capacity/performance option. Its trade-offs depend on model, format, kernel, hardware, and task:
FP16/BF16-class reference precision. Often used as a comparison baseline for supported models and hardware; it is not automatically the model’s original or “full-quality” format.
INT8 / FP8 (8-bit). May reduce weight memory or improve supported execution paths; quality and speed effects vary.
INT4 (4-bit). Can reduce weight memory further; measure quality and kernel performance for the exact artifact.
Quantization methods and file formats. AWQ and GPTQ are weight-quantization methods. GGUF is a model file format that stores tensors and metadata and supports multiple numeric representations. Check the exact quantization, artifact format and serving kernel together.
Raw parameter-count arithmetic is only a lower-bound estimate; runtime memory also includes KV cache, activations, workspaces, fragmentation, and replicas. Use the serving engine’s profiler and a load test. Evaluate output quality on the production task, not only a general benchmark.
Throughput and capacity planning
A key planning question: how many tokens/second do you need?
Measure time to first token, inter-token latency, end-to-end latency, throughput, queue time, error rate, and memory headroom across prompt/output lengths and concurrency levels.
For capacity planning:
- Estimate peak concurrent requests.
- Estimate average request length.
- Calculate total tokens/second needed.
- Add headroom derived from burst, failure, and rollout requirements.
Reliability and fallback
Self-hosting means you own reliability.
Health checks. Continuous health monitoring. Restart unhealthy instances.
Overload behavior. Use bounded queues, admission control, backpressure, and a tested degradation or rejection policy. Letting requests wait indefinitely can worsen an overload and breach latency objectives.
Fallback to APIs. A managed fallback can absorb some outages or peaks, but only if model quality, data policy, contracts, rate limits, state, and failover behavior are compatible and tested. It adds complexity and can fail concurrently.
Failure capacity. Size spare capacity or an alternative path from the availability objective and tested failure modes; every accelerator can fail, but dedicated idle hardware is not the only design.
Multi-region. Add regional capacity only where latency, residency and availability requirements justify it; every route and fallback must satisfy the data contract.
Update strategy. New model versions, server upgrades. Blue-green deployments to avoid downtime.
Managed APIs can transfer parts of this infrastructure work to a provider. Your application still owns integration, quotas, failure handling, data-route approval and the tested end-to-end outcome.
Two decision records to produce
Do not invent an anonymized outcome. Produce auditable decision records from current quotes and benchmark artifacts.
Self-host candidate record:
- model artifact, revision, license, quantization, serving version, accelerator, region, and deployment topology,
- workload distribution and quality evaluation against the current hosted baseline,
- load-test command, dataset, latency/throughput results, saturation point, and recovery behavior,
- capital or rental cost, utilization, engineering effort, security work, and expected incident cost,
- break-even range with sensitivity analysis and an exit criterion.
Managed candidate record:
- provider, model/revision behavior, region, price sheet date, quotas, and contract terms,
- equivalent quality, latency, rate-limit, outage, and data-boundary evidence,
- migration effort and vendor concentration risk,
- conditions that would trigger another self-hosting evaluation.
When to revisit the decision
The decision isn’t permanent. Periodically revisit:
Volume changes. Up significantly: self-hosting more attractive. Down significantly: less attractive.
Pricing changes. Closed APIs getting cheaper or more expensive. Managed open getting cheaper. Hardware getting cheaper.
Model improvements. New open-weight or source-available candidates that meet the workload target, or new closed models that change the quality comparison. Verify licenses and actual availability.
Operational capacity. Team grew or shrunk in ML/ops capability.
Privacy / compliance changes. New requirements that mandate self-hosting.
Set a review cadence from contract, price, model, workload, security, and capacity volatility, and add event-driven triggers. A quarterly review is an example, not a universal default.
Hybrid patterns
It is not all-or-nothing. Candidate hybrid patterns include:
Self-hosted for the bulk; APIs for the hard cases. Classification, simple generation on self-hosted; complex reasoning on closed APIs.
Self-hosted for steady; APIs for spikes. Self-hosted handles base load; APIs absorb peaks.
Self-hosted for sensitive; APIs for general. Sensitive data through self-hosted; general queries through APIs.
Self-hosted for fine-tunes; APIs for base. Custom models run yourself; off-the-shelf models from APIs.
Hybrid adds routing, data-policy, evaluation, observability, contract, and failure complexity. Adopt it only when tests show that the split improves an explicit objective.
Decide on current evidence
Choose from quality-equivalent candidates using the measured load shape, complete cost and mandatory data/security requirements. Keep the assumptions that could reverse the decision visible: capacity steps, staff time, price changes, model changes and permitted fallback routes. Assign an owner and an exit criterion for either architecture.