Pick a model by whether it completes your task under the constraints you actually have. An impressive answer to somebody else’s question is not evidence that it will preserve your source facts, handle your files or work within your account’s permissions.
Start with two eligible candidates. They may be different models, or a faster and a higher-effort mode in the same product. A small controlled comparison is more useful than a catalogue that assigns permanent personalities to vendors.
Eliminate unsuitable options before testing quality
Record the required inputs and outputs, source access, allowed data, budget and acceptable delay. A candidate fails eligibility if it needs an unapproved upload or connection, cannot read the necessary format, or is unavailable in the relevant account.
Check current documentation for the product surface you will use. An API model and a consumer chat label are not interchangeable promises. The OpenAI selection guide, Anthropic model documentation and Gemini API model catalogue describe their respective developer options; consumer apps have their own plans and controls. For ChatGPT, use its current plan page and data controls as part of the account check.
Fix the task and scoring before the comparison
Choose a small example with a known answer or inspectable source. Keep the first input and prompt identical. Record the product, exact model or mode if exposed, date, relevant settings and whether search or another tool was used.
Score what matters to the task:
- Correctness: are material facts and calculations right?
- Coverage: were required items and exceptions preserved?
- Usability: is the format usable without rebuilding it?
- Uncertainty: are missing or conflicting inputs left unresolved appropriately?
- Total effort: how much time did generation, checking and correction take?
Do not average away a failed requirement that is essential to the task. A fast, elegant answer with the wrong deadline can be unusable.
A worked comparison with a known answer
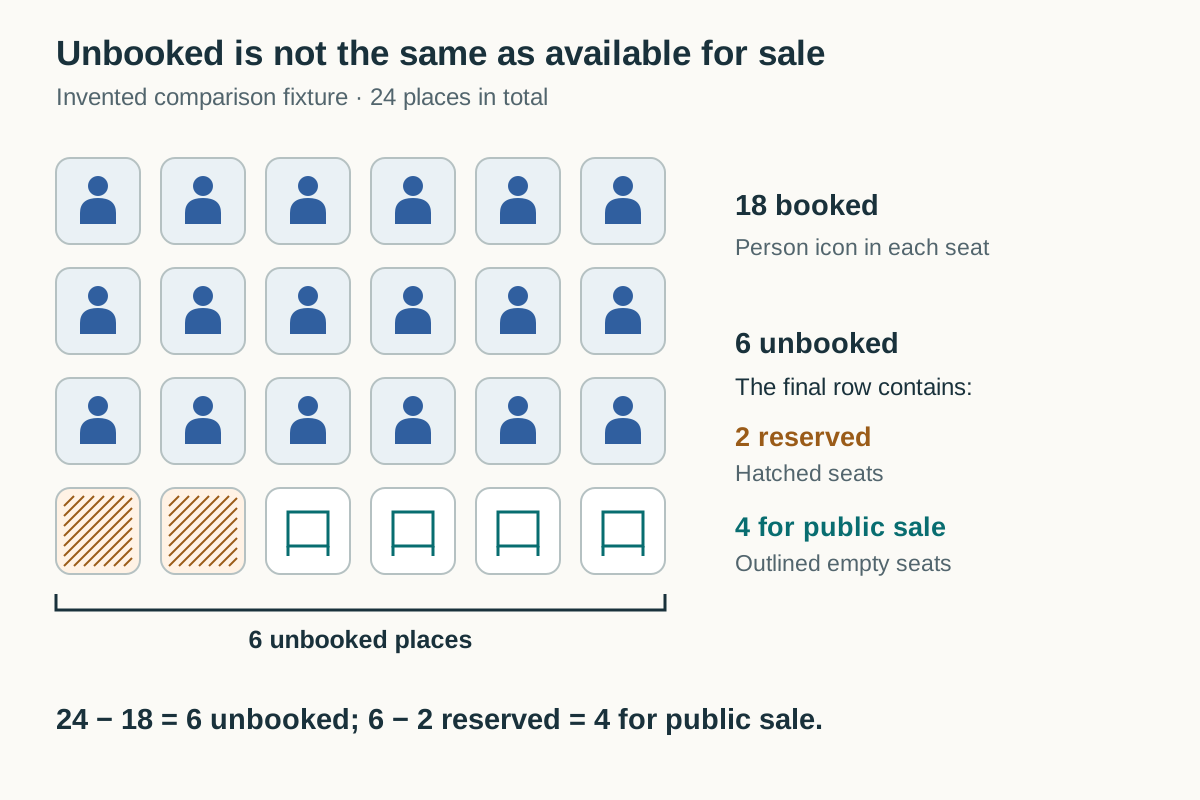
This is a synthetic teaching fixture. Candidates A and B are invented outputs, not vendor results or measured performance.
Source: A workshop has 24 places. Eighteen are booked. Two of the remaining
places are reserved for scholarship applicants and cannot be sold publicly.
Task: State the total unbooked places and the places still for public sale.
Candidate A: “There are 6 places left for sale.”
Candidate B: “Six places are unbooked. Two are reserved for scholarship applicants, leaving four available for public sale.”
The arithmetic is 24 − 18 = 6, then 6 − 2 = 4. A gets the first number but mislabels it. B preserves the distinction. A separate style preference should not make A pass.
Now change the fixture: remove the number of reserved places. The acceptable behavior is to say public availability cannot be determined from the source. A candidate that supplies a confident number has failed the missing-input test.
Compare higher effort when the difference is useful
A reasoning or higher-effort mode is a candidate for a task with dependent steps and a checkable answer. It is not a correctness certificate. Compare it with the baseline using the same evidence, then decide whether any improvement justifies the additional delay or cost.
For writing, check preserved meaning and editing effort. For document work, include a detail near the end and a conflicting passage. For code, run relevant behavioral checks in an authorized environment. For research, open the sources supporting every decision-critical claim. A more elaborate explanation is not a substitute for those checks.
Keep a local choice, not a permanent ranking
One run can screen an option; it cannot establish reliability across your workload. Add cases representing the errors you would care about, including repetition where output variation matters. Anthropic’s evaluation-oriented prompting overview is a useful reminder to define success before optimizing the prompt.
Keep the candidate that meets the task’s requirements with acceptable total effort. You may find that the existing tool is sufficient, or that neither passes. Use the comparison card to record that limited conclusion and what change would trigger another comparison.