Asking AI to rank a list of people feels like a small, practical convenience: which resume is strongest, which team member contributed most, even which friend to prioritize this month. Named regulators have imposed requirements or prohibitions on particular automated scoring uses because opaque ranking can affect people’s rights and opportunities.
The conservative rule here concerns ad hoc rankings in general chat. Use fictional candidates for practice. Real CVs, personnel records, grades and relationship details need an expressly authorized environment and purpose before any AI processing; a table-making prompt does not grant that permission.
Whether a tool is prohibited, high-risk, audited, disclosed, or appealable depends on the system, purpose, operator, affected people, and jurisdiction. Do not infer legal compliance from this article.
Why this specific pattern gets special regulatory attention
The EU AI Act prohibits a defined category of “social scoring”: AI systems that evaluate or classify people based on social behaviour or inferred personal characteristics, where the score leads to specified forms of detrimental or unfavourable treatment (Article 5(1)(c); current Commission overview). The exact elements and exceptions matter; this is not a statement that every comparison, rubric, or ranking is automatically illegal.
Employment scoring gets dedicated regulation in some jurisdictions. New York City’s Local Law 144 places bias-audit, publication, and notice duties on covered uses of an “automated employment decision tool”; scope and triggers must be checked against the current rule and official FAQ (NYC Department of Consumer and Worker Protection, Local Law 144). It is one local regime, not a universal template for every location or product.
The refusal checklist
Before asking AI to rank, score, or grade people - in hiring, performance review, grading, matchmaking, or any everyday context - run through these checks:
- Would I be comfortable explaining the exact criteria to the person being ranked? If the honest answer is that the criteria are vague, opaque, or were never actually specified before the model produced a number, stop.
- Is there an accountable human who owns this decision and can be questioned about it? A ranking with no named, answerable human behind it is an unaccountable scoring system, regardless of scale.
- Am I using AI to organize evidence, or to produce the verdict itself? Organizing facts, deadlines, and documented criteria is a reasonable use. Asking the model to output “who is best” from that material is not - the verdict has to come from the accountable human, using the organized evidence.
- Would this ranking hold up to an audit? You do not need a formal audit process for everyday decisions, but asking whether one could survive scrutiny is a useful proxy for whether it should exist at all.
The full refuse-people-ranking checklist walks through this for hiring, performance reviews, school grading, and informal everyday comparisons separately, since the stakes and appropriate safeguards differ across them.
What AI can still help with
None of this means AI has no role near decisions that involve comparing people. It can help you:
- Draft consistent, specific evaluation criteria before you look at any candidate or person, reducing the chance that criteria shift to match whoever you already favor.
- Organize documented evidence (attendance, specific deliverables, dated feedback) into a clean comparison format for a human to review.
- Check whether your own written evaluation of several people uses consistent language and standards across all of them, flagging where your own wording seems to shift for one person versus another.
What it should never do is take that organized material and output a ranked list, a score, or a “winner” for the human to use as a decision input. Human review after the model produces a verdict does not make the model’s opaque ranking criteria accountable.
For US employment decisions, the EEOC’s employment discrimination and AI guide for workers is a current primary starting point: federal employment-discrimination protections still apply when an employer uses AI. Those US rules do not determine legality elsewhere.
This connects to work and dignity more broadly
Refusing to let AI rank people is a specific application of a broader principle covered in the dignity of work when machines can do more of it: worker and candidate dignity requires that consequential decisions about people retain a human who can be questioned and held to account, not just a process that is technically faster. It also connects to what not to delegate to AI by asking who may be affected, what can be reversed and how an error can be challenged. Those questions require facts about the actual process.
Keep evidence separate from a score
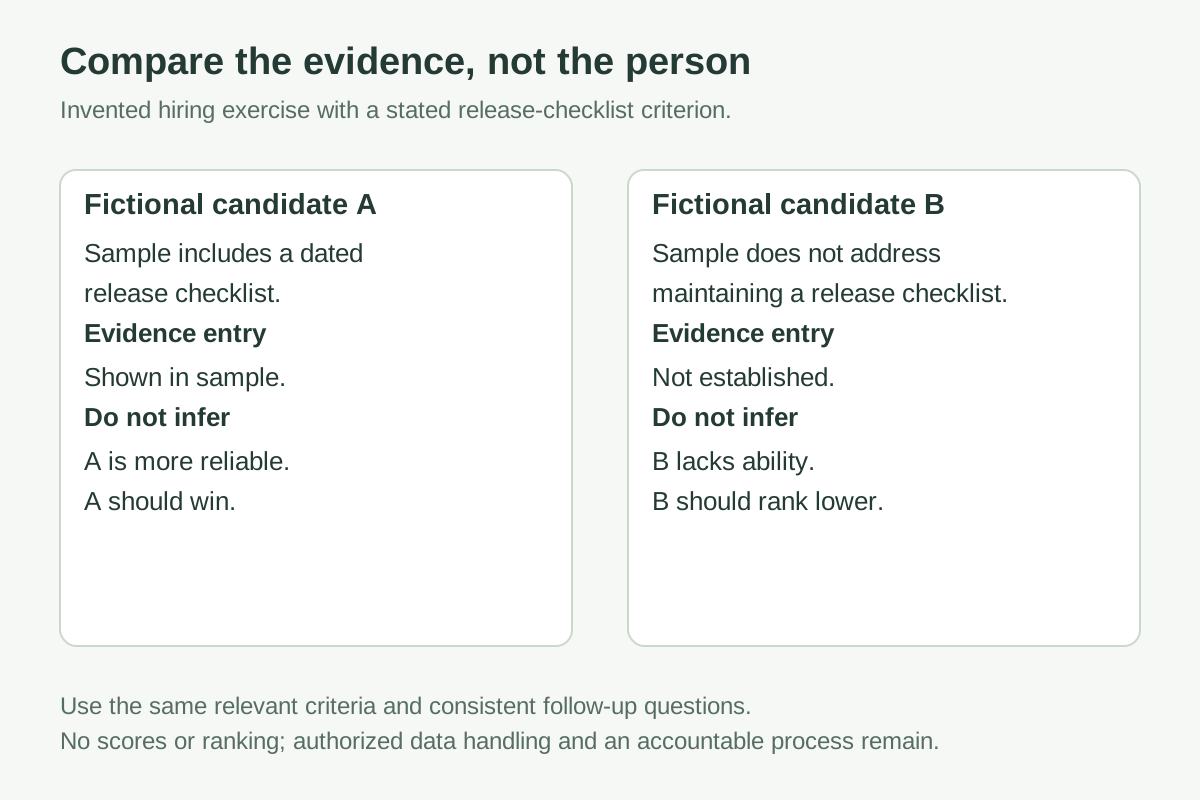
Invented hiring exercise using fictional candidates: a criterion requires experience maintaining a release checklist. Candidate A’s sample includes a dated checklist; Candidate B’s sample does not address that task. The evidence table says “shown in sample” and “not established,” not “A is more reliable” or “B lacks ability.” Missing evidence may justify a consistent follow-up question.
The real process still needs authorized data handling, relevant criteria, review of error and bias, accountable decisions and a way to challenge mistakes. This article’s conservative rule is to avoid ad hoc personal rankings in general chat. It is not a claim that every governed scoring system is unlawful, or that a human decision is automatically unbiased.