Asking a model to “check my reasoning” after stating a preferred option can anchor the response to the user’s framing. The output may repeat assumptions or produce plausible objections without retrieving evidence; it is not an independent psychological assessment.
A fixed checklist, an explicit initial leaning, and external verification can make the exercise more auditable than an open-ended request for validation. They do not guarantee that the audit detects bias or improves the decision.
A model auditing your decision is not a neutral referee. Malberg and colleagues evaluated 30 documented biases across 20 language models and reported evidence of each in at least some tested models (2025 revision of their 2024 preprint); that study is evidence about its tested models and prompts, not proof that every model behaves identically. A model can also generate plausible counter-evidence that was never retrieved. Verify anything you plan to act on.
Six biases, checked the same way every time
Use a fixed teaching list instead of relying only on an open-ended request. The checklist makes requested coverage visible; it does not force correct analysis or cover every relevant cognitive process.
| Bias | What it looks like in a real decision | The counter-question |
|---|---|---|
| Confirmation bias | You searched for reasons the option is right, not reasons it might be wrong | What did I not look for because I expected it to disagree with me? |
| Sunk cost | Time, money, or effort already spent is treated as a reason to continue (Arkes & Blumer, 1985) | If I were starting today with zero prior investment, would I choose this? |
| Availability heuristic | A vivid recent example feels more likely or important than the base rate supports (Tversky & Kahneman, 1974) | Is this actually common, or just the example I can remember most easily? |
| Status quo bias | The current state is the implicit default, and change is held to a higher evidence bar than staying put | If both options were new to me today, which would look better on the evidence alone? |
| Framing effect | The same facts, described as a gain versus a loss, produce different preferences (Tversky & Kahneman, 1981) | If I restated this option in the opposite frame (cost instead of saving, risk instead of opportunity), would I still prefer it? |
| Base-rate neglect | A specific, compelling story is weighted over the general statistical pattern it belongs to | What is the base rate for outcomes like this, before I add the specific story? |
This is a teaching set, not an exhaustive or clinically validated diagnostic instrument. It is suitable only as structured reflection on ordinary low-consequence decisions, not for labelling a person as biased, assessing capacity, or assessing mental state.
Step 1: state the leaning before the audit, in writing
Keep the original reasoning private. Before sending anything to AI, confirm the account and tool are approved for that information; ordinary decisions can contain confidential work, relationship or third-party details. Use only permitted minimal context, or practise with the fictional example below. Do not upload a private decision log merely because the decision is reversible.
Before opening a chat, write down locally:
- The option you are currently leaning toward.
- Since when you have been leaning that way.
- What would have to be true for you to change your mind.
This step makes the initial preference explicit instead of leaving the model to infer it from tone and framing. That creates a record you can compare with the audit’s findings, but the record does not prevent anchoring or confirmation bias.
Step 2: run the fixed checklist with evidence required
Weak prompt:
I'm thinking about keeping note-taking app A for our reading group instead of trying B. Is this a good decision?
This prompt supplies the preferred option and asks for an opinion. Depending on the model and context, the answer may echo that framing, oppose it, or add generic caveats; none of those outcomes is an evidence audit.
Stronger prompt:
I have already decided I am leaning toward [option]. Do not tell me whether the decision is good.

Audit my reasoning against exactly these six biases: confirmation bias, sunk cost, availability heuristic, status quo bias, framing effect, base-rate neglect.

For each one:
1. Quote the specific part of my reasoning where it might apply. If no supporting passage exists, say insufficient evidence; do not manufacture a flag.
2. State what evidence I have not yet checked because of it.
3. Propose one piece of counter-evidence that, if true, would change my decision; and be explicit about whether that counter-evidence is something I need to go verify, or something you generated as a plausible example.

Do not choose an option for me. Match the strength of each finding to the quoted evidence; a plausible concern is not a demonstrated bias.
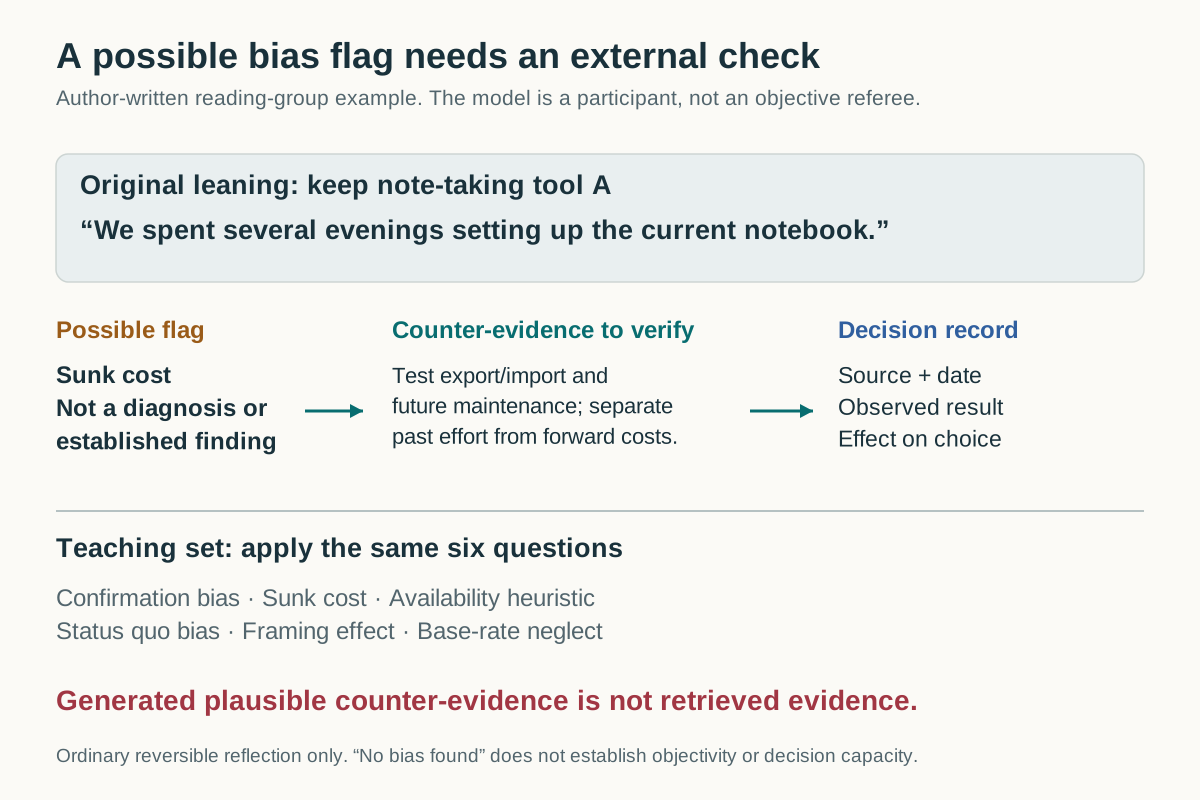
Author-written illustration, for a reading group choosing whether to keep its existing note-taking tool. The fictional reasoning supplied is: “We spent several evenings setting up the current notebook. B must prove it is better because A is already here. I want to avoid the risk of switching.” These are possible flags to investigate, not established psychological findings:
Sunk cost: Reasoning quoted: “we spent several evenings setting up the current notebook.” The expenditure already incurred is sunk, but the integration or capability it created can still change forward switching, maintenance, retraining, and opportunity costs. Evidence not yet checked: a forward-looking comparison that separates past expenditure from future stay/switch cash flows, risks, and benefits. Counter-evidence to check: test how much work export, import and future maintenance would require rather than using the effort already spent as the deciding reason.
Status quo bias: Reasoning quoted: “B must prove it is better because A is already here.” This may apply a higher evidence bar to change; actual transition costs can still justify different treatment. Counter-evidence to check: build the comparison table as if evaluating two new vendors, neither incumbent.
Framing effect: Reasoning quoted: “I want to avoid the risk of switching.” Restate the same evidence in terms of costs of staying and changing, preserving probabilities and amounts. Check whether the preference changes; the quoted sentence alone does not demonstrate a framing effect.
The illustration separates proposed checks from established facts. An actual model output must do the same. Require that distinction so generated scenarios are not mistaken for retrieved facts.
Require the model to separate “evidence to verify externally” from “illustrative reasoning it generated” in every finding. If it does not do this on its own, add a fourth instruction: “Label each counter-evidence item as [verify] or [illustrative].” Treat unlabeled output as illustrative by default and check it yourself before it changes anything.
Step 3: capture counter-evidence before you commit
For each material bias flag, collect the relevant counter-evidence rather than accepting the model’s plausible version. External verification is what distinguishes this workflow from a purely generated critique, but it does not guarantee that the evidence set is complete or correctly interpreted.
Here is an invented completed record, not evidence from a real reading group:
| Flag | Check outside the chat | Illustrative finding | Decision effect |
|---|---|---|---|
| Sunk cost | Export a copy of the notebook and inspect import requirements | The new tool cannot preserve existing source links | Retain the current tool for now because of future work, not past effort |
| Status quo | Compare both tools against the same three required tasks | Only the current tool passes all three | Record the task evidence rather than “we are used to it” |
| Framing | Restate staying as accepting current limitations | Preference unchanged | No proof that bias is absent; retain the test record |
In your own record, include the actual source, test or observation and its date. Never copy the invented findings as evidence about your tool.
If the preference remains after relevant counter-evidence is checked, the record is more explicit than the original leaning, not necessarily correct or complete. If it changes, record which evidence changed it; do not attribute the improvement to the checklist alone without a comparison.
What the audit is not for
Use this exercise for ordinary, reversible choices. It does not assess mental state or decision-making capacity, and it cannot replace qualified advice for material legal, medical or financial decisions. For immediate distress or safety concerns, turn to appropriate human support instead of extending the audit.
A “no bias found” output is inconclusive. It may reflect missing context, the checklist’s limits or the model’s own errors. Accountability remains with the decision owner; the record should say what evidence was checked and what remained unknown.
A second, independent pass
Because a single model run reflects one model’s errors layered on top of yours, compare the output with a colleague who has not seen your preference or with a qualified domain expert when stakes require it. A fresh model conversation may reduce conversational anchoring, but it is not an independent expert and can reproduce correlated errors. Investigate agreement and disagreement against evidence; divergence does not by itself mean the decision is close. How to make AI disagree with you covers one way to elicit counterarguments, not certify independence.
Keep findings proportional to evidence
Use the audit sheet to retain your initial leaning, quoted flags, external checks and final decision. “The export test changed my choice” is a supportable statement when the test is recorded. “AI removed my bias” is not established by this exercise.
The checklist earns its place if it helps you identify a relevant missing check. Completing all six rows is not the objective.