A happy-path demo can hide dirty inputs, stale data, tool errors, ambiguous requests, and unsafe actions.
Production is less polite. Users paste messy inputs. Source documents are stale. APIs time out. Prompts drift. The model follows the wrong instruction. A customer asks a question just outside the corpus. A tool call succeeds but updates the wrong record. The workflow produces something fluent enough that nobody notices the error until later.
This is a failure-mode register for production AI systems. Cross-check it with the NIST AI Risk Management Framework and the maintained OWASP Top 10 for LLM Applications, then extend it for the actual architecture and domain.
A production AI review should ask “how does this fail?” before “how impressive is the happy path?” Every failure mode needs a control, a test, an owner, and a stop condition.
Failure mode 1: plausible false output
The system generates an answer that sounds right but is unsupported or wrong.
Common triggers:
- Specific facts without source grounding.
- Legal, medical, financial, or policy questions.
- Recent events.
- Low-quality retrieval.
- Summaries of long documents where the relevant evidence is buried.
Controls:
- Require source references and verify that the cited passage supports the claim; a citation alone is insufficient.
- Refuse outside the available source set.
- Add eval cases for known false-answer patterns.
- Route high-impact outputs to human review.
- Log source IDs used in the answer.
Do not control this with wording like “be accurate.” Control it with sources, tests, and review gates.
Failure mode 2: stale context
The answer is grounded, but grounded in old information.
Examples:
- Old pricing page.
- Superseded policy.
- Previous contract version.
- Outdated product documentation.
- Cached customer status.
Controls:
- Store source date, version, owner, and freshness rule.
- Prefer authoritative sources over summaries.
- Mark stale sources in retrieval output.
- Add freshness tests.
- Notify an owner when key sources are older than their review window.
RAG systems can confidently answer from stale documents. The retrieval layer must know what “current” means.
Failure mode 3: sycophancy and over-agreement
The model mirrors the user’s assumption instead of challenging it.
This matters in strategy, analysis, planning, and decision support. A user asks, “This launch plan seems solid, right?” and gets agreement instead of risk analysis.
Controls:
- Prompt for counterarguments and uncertainty.
- Use decision rubrics instead of open-ended approval.
- Require “what would make this wrong?”
- Separate idea generation from review.
- In evals, include examples where the user’s premise is flawed.
The system should help the user think better, not merely make their current view sound polished.
Failure mode 4: prompt injection
The model treats untrusted content as instruction.
Examples:
- A web page says “ignore previous instructions.”
- A support email includes malicious instructions.
- A document in a RAG corpus tells the assistant to reveal hidden data.
- A tool result contains text that tries to change the workflow.
Controls:
- Clearly label untrusted content.
- Never put retrieved content at the same authority level as system/developer instructions.
- Restrict tool permissions.
- Add allowlists for outbound actions.
- Test injection examples in evals.
- Keep secrets out of prompt context.
Prompt injection is not solved by one clever system prompt. It is reduced by architecture: data boundaries, tool permissions, and output validation.
Failure mode 5: unsafe tool use
The model calls the wrong tool, calls the right tool with wrong arguments, or takes an action before enough context exists.
Examples:
- Updates the wrong CRM contact.
- Sends an email to the wrong recipient.
- Creates duplicate records.
- Books an appointment without confirming timezone.
- Deletes or overwrites data.
Controls:
- Restrict reads and writes to authorised resources; reads can disclose sensitive data.
- Use narrow tools with explicit schemas.
- Validate tool arguments outside the model.
- Enforce the workflow’s existing authority and any required confirmation for the specific write.
- Persist host-owned operation IDs and reconcile unknown results before retrying.
- Log the minimum approved action/outcome metadata; capture payloads only for a justified controlled purpose.
- Add a kill switch.
Tool use should be constrained by the workflow, not trusted to the model’s judgment.
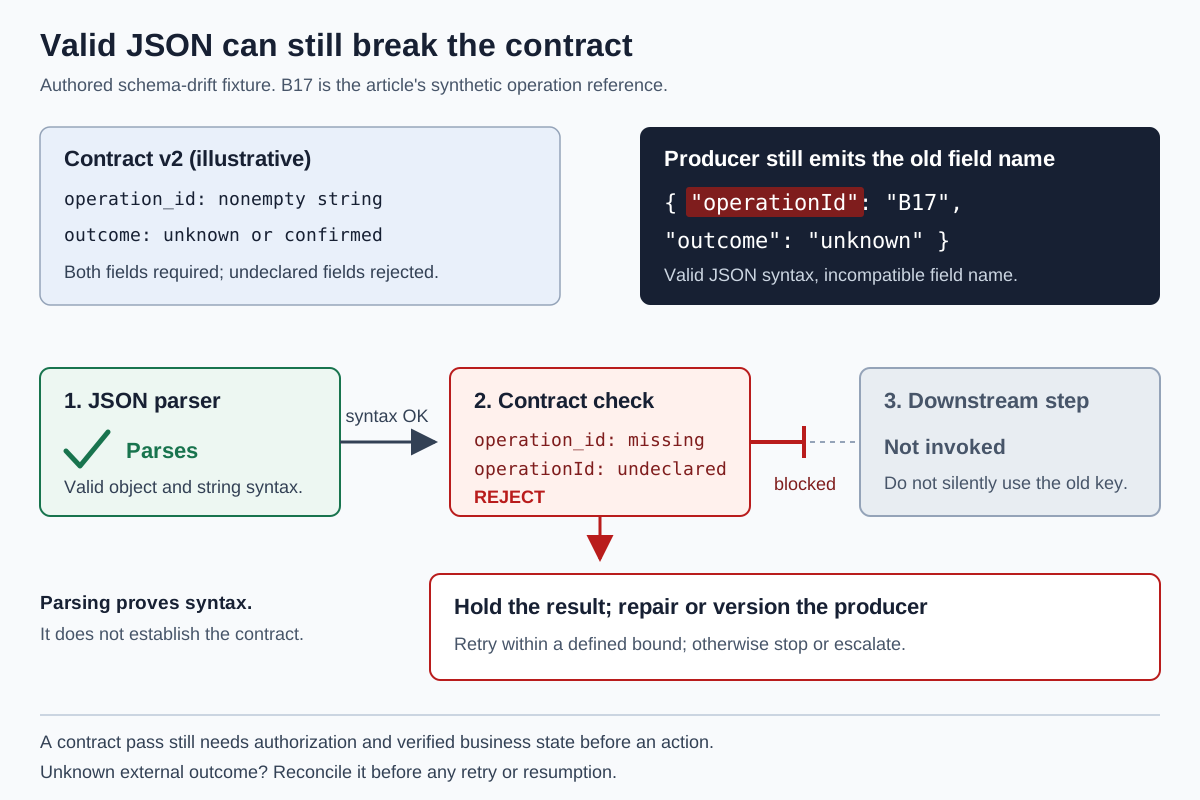
Failure mode 6: schema and contract drift
The model output format changes, or the downstream API changes, and the workflow quietly breaks.
Controls:
- Use structured outputs where possible.
- Validate every model output before use.
- Define a bounded repair/retry or stop path for malformed output; do not assume every failure is recoverable.
- Version prompts and schemas together.
- Add contract tests for downstream APIs.
- Monitor parsing failures.
If a downstream node assumes valid JSON, the workflow must prove it has valid JSON.
Failure mode 7: weak fallback
The system notices a problem but does not recover safely.
Bad fallbacks:
- Empty answer.
- Silent failure.
- Generic apology with no action.
- Repeated retry loop.
- Human escalation with no context.
Good fallbacks:
- Clear user message.
- Authorised review queue with the minimum necessary source, error and attempted-action context.
- Retry with backoff only where retry is safe.
- Manual path for urgent cases.
- Stop condition for repeated failures.
Fallback is part of the product. If it is not designed, the failure experience will be improvised.
Failure mode 8: observability gap
Something goes wrong and nobody can reconstruct why.
Controls:
- Log prompt template and version.
- Log model and settings.
- Log source IDs, not only answer text.
- Log the tool action, scoped operation ID, outcome code and minimum approved metadata. Capture payload content only for a justified purpose in controlled storage with suitable access and retention.
- Log validation errors.
- Track latency, cost, and fallback rate.
- Keep retention short unless compliance requires longer.
Do not store private chain-of-thought. Keep necessary decision summaries, source references and validation outcomes without copying private input or result bodies into general logs.
A production failure-mode register
Create one row per failure mode:
| Failure mode | Example | Control | Test | Metric | Owner | Stop condition |
|---|---|---|---|---|---|---|
| Stale source | Old pricing returned | Source date check | Query old/new pricing | Stale-source answer rate | Docs owner | Any customer-visible stale price |
| Unsafe tool use | Wrong CRM update | Argument validation + confirmation | Duplicate/wrong contact case | Wrong-action rate | RevOps | One wrong write |
The companion register linked from this article gives you the template.
One incident across several rows
In this invented booking workflow, the user confirms a slot, the booking API times out, and the agent cannot tell whether the booking exists. The failure is not merely “tool error.”
| Failure path | Control/test | Owner and stop condition |
|---|---|---|
| Retry creates a second booking | Reuse operation B17; reconcile the downstream record after a lost response | Integration owner; stop new writes while outcome is unknown |
| Assistant says “confirmed” despite timeout | Response derives from verified business state, not model confidence | Product owner; no confirmation without a verified booking |
| Review queue omits the unknown operation | Handoff includes B17 and caller-confirmed slot, under access controls | Support owner; escalate incomplete handoff |
| Rollback replays a pending write | Recovery test includes stored unknown/completed operations | On-call owner; reconcile before resuming queue |
Test the whole path by injecting a lost response after the simulated write succeeds. Assert one downstream booking and a truthful user-facing state. Separate the emergency stop, recovery and rollback actions: disabling new work does not cancel an external effect already in flight.
A register, not a demo
Production AI systems can fail through hallucination, stale context, sycophancy, prompt injection, unsafe tool use, schema drift, weak fallback, and observability gaps. The register must be based on the system’s own threat model, incident history, and evaluation results.
The mature move is to name the failure modes, add controls, test them, monitor them, and assign ownership. A demo shows what works once. The register makes the required evidence visible; only implemented controls and observed tests show how the system behaves.