“Private AI” gets used to mean everything from “we turned off training on our SaaS account” to “we run open-weight models on our own infrastructure.” Those are not the same control boundary.
For SMEs, the right private AI architecture depends on the data, the task, the quality requirement, and the team’s ability to operate infrastructure. The most private option is not always the best option. The most capable option is not always acceptable for the data. The cheapest option can become expensive if it needs constant engineering attention.
This article gives a decision map. Pair it with the primary GDPR text, NIST AI Risk Management Framework, vendor contracts and data-control documentation, and the selected serving engine’s security guidance such as vLLM security.
Define the permitted data flow and required task quality together. If no candidate satisfies both, use an approved manual or no-AI path.
The five deployment patterns
| Pattern | What it is | Candidate fit | Main limitation |
|---|---|---|---|
| Enterprise SaaS | Contracted service with verified plan-specific controls | Work whose data contract and quality requirements it meets | External processing and plan/control limits |
| VPC or private cloud | Managed model endpoint inside controlled cloud boundary | Confidential workloads needing stronger isolation | Higher cost and setup |
| Self-hosted inference | You run open models on your own infrastructure | Restricted data, custom models, scale economics | Operations burden |
| Local-device models | Model runs on laptop, workstation, or edge device | Offline, sensitive, low-latency narrow tasks | Smaller models and device limits |
| Hybrid routing | Route each use case to the matching boundary | Mixed-sensitivity portfolios | Requires classification discipline |
Personal consumer accounts usually do not provide the organization’s centrally governed identity, retention, connector, contractual, and audit configuration. Company policy should define whether they are allowed at all and for what data.
An organization may need one pattern or a governed portfolio. The goal is to choose and revalidate a boundary for each approved use case rather than treating one product label as permanent assurance.
Classify the data first
The four buckets below are an illustrative starting taxonomy. Align names and handling rules with the organization’s actual information-classification and legal requirements:
| Data | Examples | Default AI boundary |
|---|---|---|
| Public | Website copy, published docs, public research | Approved tool after rights, authenticity, prompt-injection, and terms checks |
| Internal | Process notes, properly de-identified examples, non-sensitive drafts | Approved service or controlled deployment after data-flow review |
| Confidential | Customer data, contracts, source code, financials, strategy | Enterprise SaaS with controls, VPC, or self-hosted |
| Restricted | Health data, legal privilege, HR investigations, regulated records | Legal/security review; an approved local, VPC, self-hosted, or no-AI route may be required |
This classification prevents a common mistake: using the same assistant for public blog drafts and confidential customer records because it is convenient.
Credentials, private keys, authentication tokens, and recovery codes are not a model-routing category. Exclude them from prompts, retrieval corpora, telemetry, and model-accessible tools; use a secrets manager and narrowly scoped runtime injection where a deterministic integration requires a credential.
Pattern 1: Enterprise SaaS
Enterprise SaaS may be the lowest-operational-complexity candidate. Product names, plan entitlements, and contract terms change; verify each shortlisted plan for:
- Contractual data-use and model-training terms.
- Admin controls.
- SSO and access management.
- Retention controls.
- Audit logs.
- Security documentation.
- Vendor support.
These controls may support approved work, but purchasing a plan does not establish that a particular data category or workflow is lawful or safe.
The key is configuration. Buying the team plan is not enough. Set retention, sharing, connector access, approved workspaces, and data rules.
Pattern 2: VPC or private cloud
VPC/private-cloud patterns are candidates when data may leave the application but must stay inside a defined cloud and contractual boundary. “Inside a VPC” does not prove that every control-plane, model-service, log, support, or backup path stays there; map and test the complete data flow.
- Customer support assistant over confidential tickets.
- Internal knowledge assistant over sensitive docs.
- Document extraction for contracts or invoices.
- Domain-specific assistant where you need stronger data isolation than SaaS.
Potential advantages to verify:
- Stronger isolation under the selected service design.
- More control over networking and logs.
- Evidence that may satisfy defined procurement requirements.
- A different operational split from full self-hosting.
Potential limitations to price and test:
- Pricing may exceed a shared SaaS plan for the measured workload.
- Additional integration and platform work.
- Model choice can be narrower.
- You still depend on provider infrastructure.
Treat this as one middle-ground candidate, not the default for every SME.
Pattern 3: Self-hosted inference
Self-hosting means you run the model runtime: vLLM, TGI, SGLang, llama.cpp, Ollama, or another serving stack. It makes sense when:
- Data cannot leave your environment.
- You need a custom or fine-tuned open model.
- Inference volume is high enough to justify infrastructure.
- Latency or availability needs require direct control.
- You have people who can operate it.
Do not self-host only because it feels pure. The operational cost is real: GPU capacity, monitoring, upgrades, security patches, model evaluation, scaling, and incident response.
Self-hosting is a strong choice for the right organization. For a small team without ML infrastructure experience, it can become a fragile side project.
Pattern 4: Local-device models
Local models are candidates for privacy-sensitive individual work when the whole device, update, telemetry, backup, and access boundary is controlled:
- Summarizing local notes.
- Drafting from private documents.
- Classifying internal snippets.
- Offline field work.
- Edge workflows where latency matters.
The quality tradeoff is task- and model-specific. Evaluate the local candidate on representative summarization, classification, extraction, or drafting tasks instead of assuming either parity or inferiority.
Use a local model only when it meets the task evaluation and the complete local boundary is approved; “runs on device” does not by itself prove privacy.
Pattern 5: Hybrid routing
A hybrid candidate can route workloads by approved data class:
- Public and low-risk tasks go to enterprise SaaS.
- Confidential retrieval happens inside a private RAG system.
- Restricted extraction uses only a specifically approved local, VPC, self-hosted, or no-AI route after the complete data flow is reviewed.
- Final drafting uses a different provider only if the remaining content and destination are explicitly approved. Redaction alone does not prove de-identification or permit a new route.
- Logs and evals decide whether each route is working.
Hybrid routing can match different records to different approved boundaries. It requires enforceable policy, not prompt-only classification:
- Data classification before routing.
- Redaction where possible.
- Clear model/tool allowlist.
- Logs that record which boundary was used.
- An approved fallback or fail-closed/manual path when the private model cannot do the task; no automatic cloud upload.
Decision framework
Ask six questions:
- What data enters the model? Public, internal, confidential, restricted.
- What output impact exists? Draft, recommendation, decision, customer-facing action.
- What quality is required? Define task-specific accuracy, safety, latency, refusal, and human-review targets rather than labels such as “expert-level.”
- What latency is required? Interactive, batch, real-time, offline.
- What operating capacity exists? No infra team, app team, platform team, ML ops.
- What proof do customers or regulators need? Vendor docs, logs, data residency, audit trail, isolation.
Then choose the lowest-complexity pattern that satisfies the data and quality needs.
Do not do this yet
Do not self-host before measuring the workload and quality requirement.
Do not send restricted data to consumer tools.
Do not assume “open source” means private. It is private only if deployment, logs, access, and data flow are private.
Do not deploy an AI gateway without identity-aware, policy-enforced data classification and deny-by-default routes. A centralized gateway can enforce policy, but only if bypasses, fallbacks, logs, and failure behavior are tested.
Do not ignore evals. Private but wrong is still wrong.
A practical SME starting point
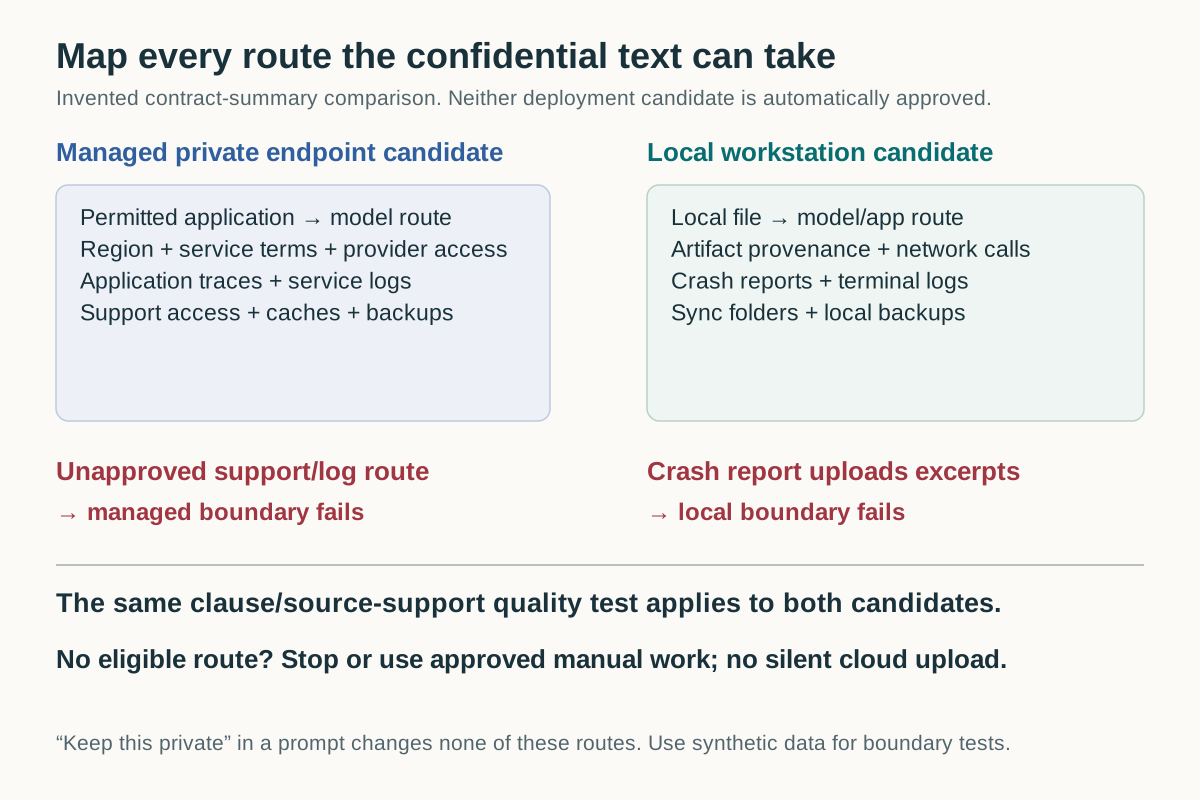
Choose one valuable use case and map its data before buying several deployment patterns. Here is an invented comparison for a confidential contract-summary workflow; neither column is automatically approved.
| Path | Managed private endpoint candidate | Local workstation candidate |
|---|---|---|
| Document | Application sends permitted text through the configured service route | Application reads the local file |
| Model | Verify inference region, provider access and service terms | Verify model/app network calls and artifact provenance |
| Evidence/logs | Check application traces, service logs and support access separately | Check crash reports, terminal logs and shared-device access |
| Copies | Verify retention, indexes, caches, backups and deletion | Check sync folders, disk encryption and local backups |
| Failure | Queue or stop unless another destination is approved | Stop or manual review; do not silently upload to cloud |
| Quality | Same clause/source-support test and unresolved-answer policy | Same test, including long-document coverage |
The local app fails the intended boundary if its crash report uploads document excerpts. The managed path fails if an unapproved support or log route receives them. A prompt saying “keep this private” fixes neither problem.
Record one candidate in the deployment decision matrix, test its complete flow with synthetic data, and compare the task outcome. Add another pattern only if a demonstrated requirement justifies its extra ownership. The OpenAI data-control documentation, for example, distinguishes endpoint and retention behaviour; an account-level training statement is not a complete data-flow description.
Architecture matched to data, risk, and operations
Private AI is architecture matched to data, risk, and operations. A portfolio may be appropriate, but every route needs an explicit owner and verified boundary.
Choose based on data, impact, quality, latency, operations, and evidence.