Using one model for every call can be unnecessarily expensive, but routing is not automatically an improvement.
A team may discover that classification, extraction, drafting, and hard reasoning have different quality and latency requirements. Routing can exploit those differences. It can also add a classifier call, provider failure modes, inconsistent safety behaviour, and more evaluation work. The only defensible savings claim is the one calculated from your measured tokens, current provider prices, and quality gates.
This is multi-model orchestration: selecting a model or specialised service for a defined call type under explicit quality, latency, privacy, and cost constraints.
This article covers the patterns, the routing logic, the trade-offs, and a step-by-step guide to implementing it.
Establish an eligible baseline
One model may be entirely adequate. Split the workload into call types only when they have distinct requirements you can evaluate, such as intent classification, a source-grounded reply and an operator handoff summary.
For each type, list required data permissions, tool/schema support, quality checks, latency and failure behavior. Exclude candidates that cannot meet those requirements before comparing price. A local model can still send data through tools; a compatible API does not establish equivalent behavior.
Record current provider prices and the exact configuration at evaluation time. Do not attach “cheap”, “fast” or “best at code” permanently to a model family. Measure the candidates on the same cases.
Calculate savings from telemetry
For each call type, collect:
- monthly call count;
- input, cached-input, and output token distributions;
- retry and cascade rate;
- tool, search, batch, or hosting charges;
- latency percentiles; and
- pass rate on the route’s release eval.
Calculate each candidate route with current prices and consistent per-token units. Separate cached from uncached input so it is not counted twice:
monthly route cost = calls × (
  uncached_input_tokens × input_price
  + cached_tokens × cached_price
  + output_tokens × output_price
) + tool_charges + hosting + expected_retry_cost
Compare that with the baseline only for candidates that pass the same quality and safety release criteria. Report the assumptions beside the result. A route that saves token cost but increases manual correction, incidents, or latency may cost more overall.
OpenAI’s evaluation guidance supports task-specific criteria, representative cases and continuous evaluation. Apply that method to the router and each fallback, not only the primary model.
If telemetry is unavailable, run a shadow evaluation first. Do not publish a savings percentage from a generic traffic split.
The basic orchestration patterns
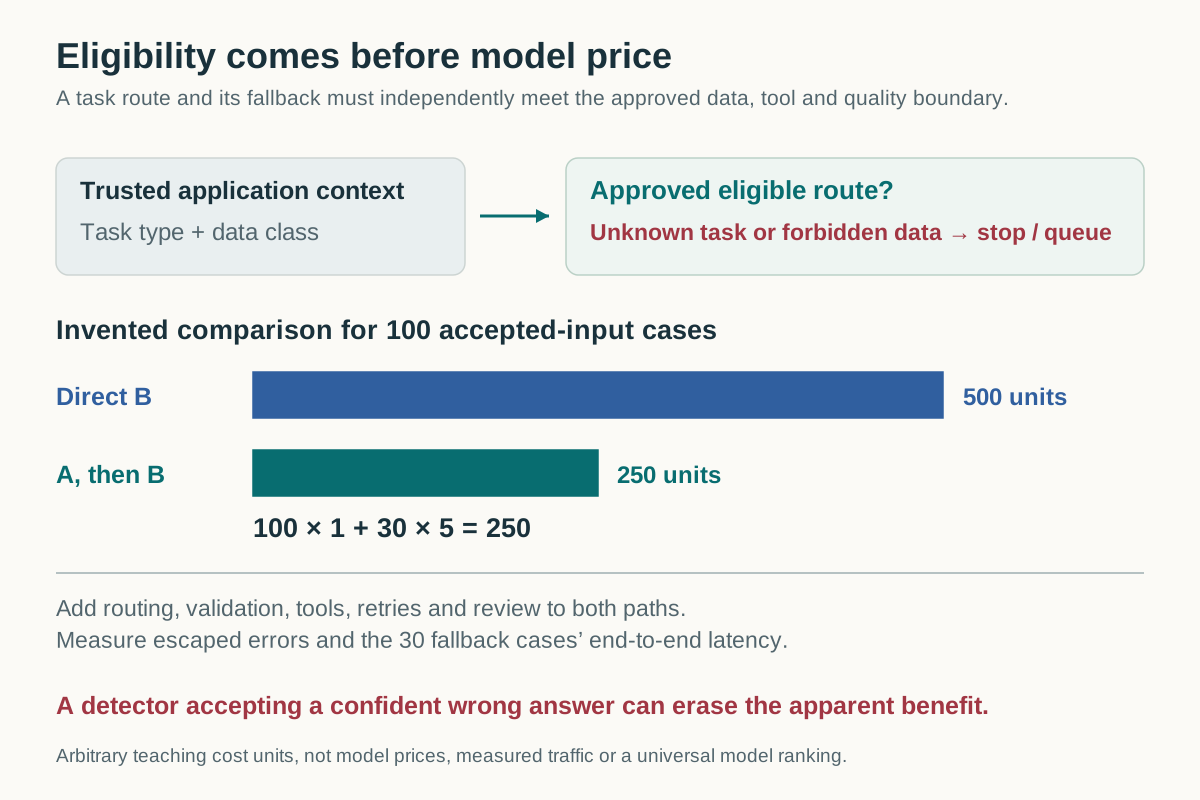
Task routing uses a task type supplied by trusted calling code to select an evaluated configuration. Unknown types should return an explicit error or review route, not fall through to an arbitrary model.
A cascade tries one configuration and escalates after a defined failure. A schema validator can catch malformed output but cannot establish factual correctness. A model judge needs its own measured errors; self-reported confidence is not sufficient acceptance evidence. Include both attempts in cost and latency.
Provider fallback is allowed only to an already approved destination that meets the same data, regional, tool and quality requirements. A timeout must not silently authorize a new provider. If no eligible fallback exists, queue or fail explicitly.
A learned router can be useful, but it adds a classifier and another failure mode. Request length, similarity and a “complexity” score are features to evaluate, not proof that a smaller model can solve the request.
A realistic example: customer support AI
For a support workflow, classify the requested help, retrieve authorized evidence, then draft or escalate. The same model may handle every generation step until measured failures or costs justify another route. Keep policy-enforced security escalation separate from model selection.
Consider this invented cost comparison. The units are arbitrary illustrative cost units, not current provider prices or measured traffic:
| Design for 100 accepted-input cases | Assumed model-call cost | Total |
|---|---|---|
| Direct candidate B | 100 calls at 5 units | 500 |
| Candidate A, then B on 30 cases | 100 at 1 unit + 30 at 5 units | 250 |
The cascade’s arithmetic is cheaper before router, validation, tooling and review costs. It is eligible only if the acceptance detector actually rejects the failures that matter. If A confidently returns a wrong answer and the detector accepts it, the apparent saving purchases a worse service.
The 30 escalated cases also wait for A before B. Measure their end-to-end latency separately; average latency can hide those delayed users. Record observed escape errors and false escalations on held-out cases before selecting the route. The route decision record keeps that evidence next to the cost calculation.
The routing logic
Keep routing policy outside the prompt. This schematic code demonstrates fail-closed task selection; configuration objects and provider calls still need an implementation and tests:
def choose_route(task_type, data_class, approved_routes):
    route = approved_routes.get(task_type)
    if route is None:
        raise ValueError("No approved route for task")
    if data_class not in route.allowed_data_classes:
        raise PermissionError("Data not approved for route")
    return route
Derive task_type and data_class from trusted application context. Do not let request text change its own data classification. Apply the same eligibility check to a fallback; record the selected route and reason without logging raw private payloads.
Tool execution needs separate controls. If a failed model attempt already caused a write, invoking another model must not repeat it. Use stable business-action keys and reconcile unknown external results before retry. A generation retry and a business-action retry are different operations.
The pitfalls
A few mistakes to avoid:
Pitfall 1: Optimising for cost while degrading quality
It’s easy to route everything to small models and watch the cost drop. It’s harder to notice that quality also dropped. Always pair routing changes with quality monitoring.
A useful discipline: shadow or A/B test a cheaper route until the sample covers important input classes and failure modes. A fixed week is not evidence by itself. Do not ship the change unless the predeclared quality and safety criteria hold.
Pitfall 2: Over-engineering the router
A router with many task types and opaque logic can be harder to maintain than the routing it replaces. Start with the smallest number of routes your measurements justify.
Add a route only when it changes an operational decision and improves a measured constraint enough to justify its ownership, tests, and fallback path.
Pitfall 3: Ignoring latency
Lower-priced models are not necessarily faster. Measure latency and quality separately. A cascade (try one model, then fall back) adds at least one extra attempt for fallback cases and can materially increase tail latency in user-facing flows.
For a user-facing latency-sensitive response, evaluate a direct route against a cascade on both pass rate and tail latency. Cascades are often easier to tolerate in batch or asynchronous work, but the correct route is workload-specific.
Pitfall 4: Not handling provider failures
When you depend on multiple models, you have multiple ways to fail. A flagship model goes down, a rate limit kicks in, an API key expires. Your routing logic needs fallbacks.
Define explicit behaviour for rate limits, timeouts, and provider errors. A cross-provider fallback is appropriate only if its data-processing terms, regional path, tool/schema contract, and eval results are acceptable. Otherwise fail closed, queue, or escalate; returning a materially worse answer is not availability.
Pitfall 5: Not measuring per-route quality
You need to know which route is doing well and which isn’t. This means evaluation, ideally automated.
Log route/configuration version, case reference, token and latency totals, retries, validator outcome and an approved quality signal. Raw requests and responses require separate permission, minimization, access and retention. Use protected sampled cases for review when authorized; do not turn the routing dashboard into an unrestricted copy of customer data.
Revalidate live dependencies
Model IDs, retirement dates, context limits, prices, rate limits, regional processing, and structured-output/tool semantics can change independently. Review live provider documentation and rerun route evals before changing an alias. An OpenAI-compatible transport does not guarantee equivalent schemas, tool behaviour, token accounting, safety policy, or data handling.
Route only where evidence supports it
Publish the comparison’s sample, configuration, quality criteria and cost assumptions. Keep a rollback route and re-evaluate after model, prompt, provider terms or traffic changes. If no measured constraint improves enough to justify the extra operational work, retain the single eligible model.