AI coding tools can help a non-developer turn a narrowly defined requirement into a prototype. Tools such as Cursor and Claude Code can propose files, run commands, and help investigate failures, but they cannot certify that the result is correct, secure, maintainable, or fit for production. The person using the tool remains responsible for understanding the data, permissions, tests, and consequences.
This guide describes a bounded learning workflow for non-developers: what is reasonable to prototype, which evidence to retain, and where experienced engineering review becomes mandatory.
What you can realistically build
Choose a local task whose expected output you can calculate yourself and whose failure is easy to undo. A script transforming an invented CSV, a small browser demo or a static page can meet that boundary. A “simple” bot connected to real customer records may not.
The deciding factor is the consequence and your ability to test it, not the application’s size. Identity, payments, sensitive data, concurrent writes and safety-critical behavior require expertise beyond checking a pleasant-looking demo. Keep those out of the first exercise.
The tools
Cursor’s Agent tools can inspect and change a project and run commands. Claude Code’s security documentation describes its permission boundaries. Check the current settings before use: code editing, terminal execution and network access are different grants.
Use the tool your environment permits, in a disposable project directory with invented data. Do not add cloud hosting, a database or another provider merely because the generated plan suggests it. The exercise below needs a local Python runtime and standard library only; it does not need a model API inside the program.
The mental model
Working with AI coding tools as a non-developer requires a slight reframe.
You are still participating in software development even if you are not typing most of the code. The model translates some intent into candidate code. Your job is to:
- Describe what you want specifically and concretely.
- Test that it does what you want.
- Notice when something is off and describe what.
- Keep the system simple so you can understand what you have.
Clear requirements help, but they do not replace engineering knowledge. You define observable outcomes, review the diff, test normal and failure paths, and ask an experienced engineer to review anything you cannot safely evaluate yourself.
Build in small, observable steps
Each step should leave something you can inspect: a file, a diff or a test result.
1. Build small, build often
A large one-shot request makes requirements, changes, and failures difficult to isolate. Break the work into observable increments and require a test or inspection result after each one.
The fix is to build incrementally. Start with the smallest useful version. Test it. Add the next feature. Test it. Add the next.
A first project might evolve through small, testable increments like these (the labels are stages, not time estimates):
- Stage 1: “Make a script that reads a synthetic CSV and prints the rows where the email domain is .ee.”
- Stage 2: “Now make it also filter by signup date. Take the date as a command-line argument, validate it, and add tests for invalid dates.”
- Stage 3: “Now make it output a clean Excel file instead of printing. Preserve the original file and test empty and malformed input.”
- Stage 4: “Only after the script passes: propose a local web interface where I can upload the CSV and download the result. Explain upload limits, file deletion, and threat boundaries before coding.”
Each stage should produce a verifiable artifact. Whether it becomes a useful tool depends on the tests, data, environment, and reviewer competence; there is no reliable universal completion time.
2. Test every step
Each time the AI changes something, test it. Run the code. Look at the output. Confirm it matches what you expected.
This sounds obvious. The temptation, when the AI says “I’ve updated the script,” is to trust it and move on. Don’t. Run it. The model sometimes reports a fix that did not land. The faster you catch this, the cheaper it is to fix.
A practical habit: after every meaningful AI change, run the code. If you don’t run it, you don’t know if it works.
3. Read the code (a little)
You don’t have to understand the code line by line. But you should at least glance at what changed. Often you’ll notice something obvious: “wait, you removed the date filter; that wasn’t supposed to change.”
Use the diff view to check whether the change stayed inside the requested files and preserved earlier behavior. If you cannot assess a material change, ask for an explanation and independent engineering review before relying on it.
4. Use git, even alone
Git is version control. It lets you save snapshots of your project and roll back if something breaks. Cursor and Claude Code can use git for you; you just ask: “commit this with the message ‘add date filter’.”
The discipline:
- After each meaningful change, commit.
- When the AI breaks something in a way you can’t easily fix, ask: “roll back to the previous commit.”
- For bigger changes, create a branch first (“create a new branch called ‘add-email-feature’ and work there”).
Git can return tracked files to a committed state. It does not automatically protect untracked files, uncommitted work, databases, external services, or secrets, so keep tested commits and separate backups for stateful data.
5. Use a single small project at a time
The “many tools, one project at a time” rule. Resist the urge to have five half-built projects. Pick one, finish it (or get it to a useful state), then move on.
This matters because each project has its own context: its files, its dependencies, its quirks. When you switch projects, verify the working directory, instructions and available files before allowing edits. A previous conversation does not establish the current repository state.
A worked example: filtering an invented CSV
This is an exercise specification, not a report of a tool built for a customer. It stays local and uses invented addresses.
Create sample.csv from the following text:
id,email,signup_date
1,person@studio.ee,2026-09-01
2,person@studio.example,2026-09-02
3,person@studio.ee,2026-08-31
4,person@studio.ee.example,2026-09-03
5,person@STUDIO.EE,2026-09-04
Ask your coding tool:
Build a Python standard-library command-line script named filter_signups.py.
Inputs: CSV path, ISO cutoff date, and a new output CSV path.
Keep rows whose email domain ends in .ee, case-insensitively,
and whose signup_date is on or after the cutoff.
Preserve column order and original field text. Do not modify the input.
Reject missing columns, malformed dates and a pre-existing output path.
Validate all rows before writing any output; no partial output on failure.
No network, model calls, dependency installs or additional features.
First state the acceptance cases; then implement the smallest version.
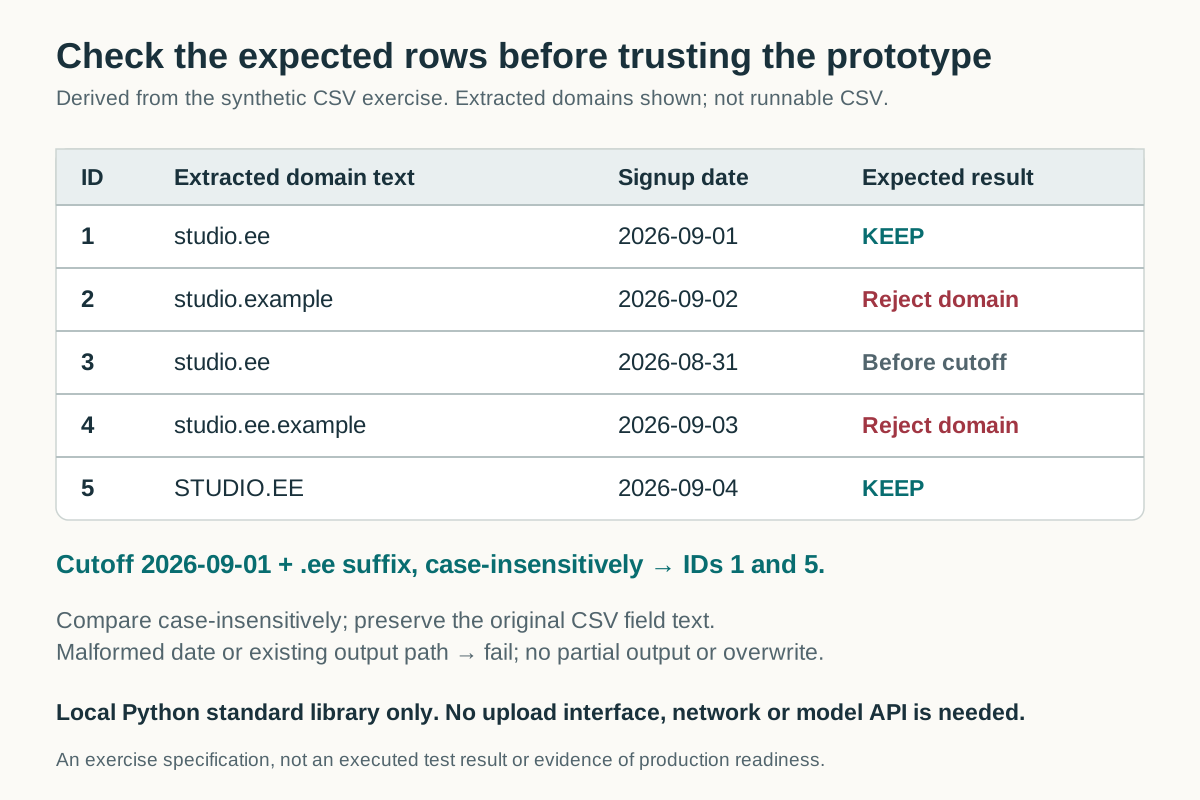
With cutoff 2026-09-01, the output should contain IDs 1 and 5, in that order. ID 3 is too early. ID 4 is not an .ee domain: matching the substring .ee anywhere would be a bug. Case-insensitive comparison should not rewrite the uppercase address in the output.
First increment: read the CSV and report its column names and row count. Check the five rows against the file. Second: validate and filter, still without writing. Check the selected IDs. Third: write to a new file only after all validation passes. Open it yourself and compare the values.
Run boundary tests that could reveal real mistakes:
| Change | Expected behavior |
|---|---|
| Cutoff equals a row’s signup date | Include it if its domain qualifies |
Cutoff is 2026-02-30 | Clear error; no output file |
| Last input row has an invalid date | Entire run fails; no partially filtered file |
email column is missing | Clear schema error |
| Existing output path is supplied | Refuse to overwrite |
| Valid file has no matching rows | Header-only output, no invented rows |
Keep these cases in the prototype acceptance record. Save the command, exit status and observed output rather than an AI statement that “tests passed”. If a failure leads to a patch, rerun both that case and the previously passing selection case.
Once this works, ask for a README that describes the input contract, how to run the script and how failures behave. Compare those instructions with the actual commands. Do not add a web upload interface until you understand the new access, file-handling and deployment boundary it would create.
The traps
A convincing demo can hide an overwrite, a silent bad-row skip or a network upload you did not request. Inspect both the output and the operations used to produce it.
If consecutive patches fail the same acceptance case, preserve the error and reduce the example. Do not let the agent change unrelated files until something happens to work. Restore a tested state only after checking for uncommitted work you need to keep.
A passing invented fixture establishes that case in that environment. It does not establish safe handling of arbitrary files or private customer data. Expand the tests and obtain the needed expertise before expanding the tool’s use.
When to actually hire a developer
Some signals that what you’re trying to build has grown beyond AI-coding-as-a-non-developer:
- You can’t describe the problem any longer; you have to describe code.
- The tool has availability, concurrency, performance, backup, or incident-response requirements you cannot test.
- You’re handling sensitive data (customer PII, financials, health) and the failure mode involves data loss or leak.
- You need integration with complex enterprise systems.
- You can no longer explain or independently test the relevant code and dependencies; line count alone is not a useful safety threshold.
- You’re hitting bugs that the AI can’t fix, and they keep recurring.
At any of these thresholds, bring in an experienced engineer. A tested prototype can clarify requirements, but the engineer may keep, replace, or redesign it after reviewing the code, data flows, and operational risks.
This is a healthy pattern: non-developer builds prototype, developer productionises. Both kinds of work are real and they complement each other.
Keep the handoff useful
If an engineer takes over, give them the requirement, source code, tested revision, acceptance cases, observed failures and intended data boundary. They may retain or replace the implementation. That evidence makes the prototype useful even when its code is not suitable for production.